ARTICLE · 1234812
研发执行Agent:基于设计文档的代码生成、审查与质量门禁
研发执行Agent:基于设计文档的代码生成、审查与质量门禁
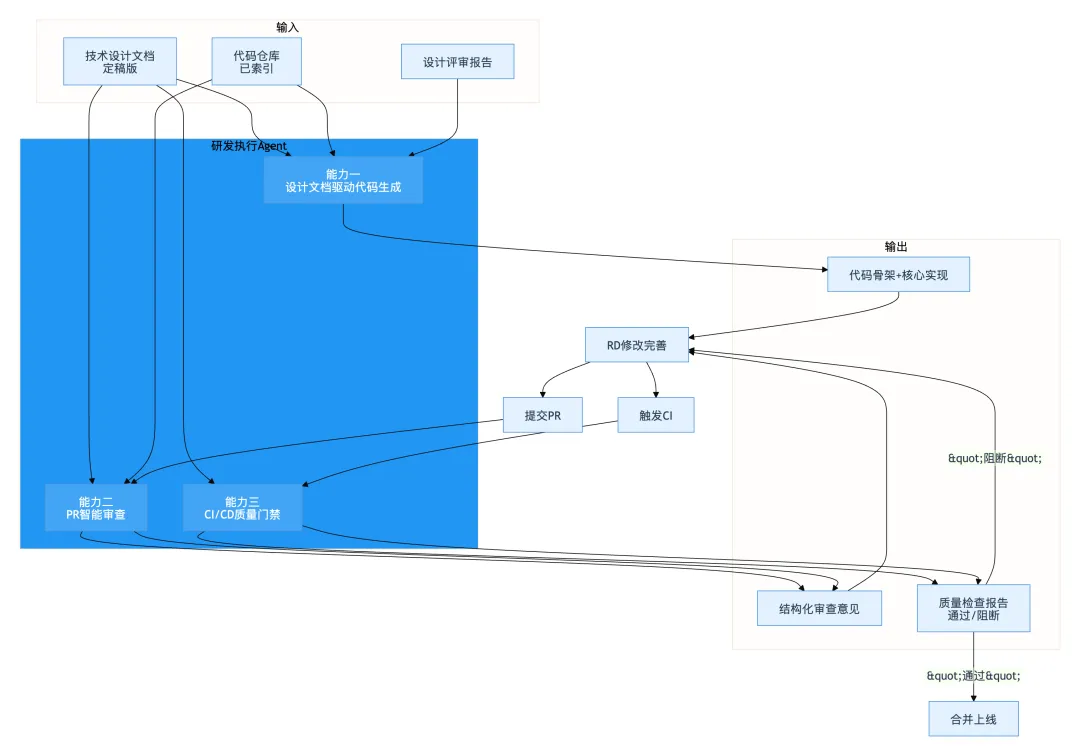
本文聚焦研发全生命周期中的第三阶段——研发执行。技术设计文档定稿后,RD进入编码阶段。研发执行Agent不是简单的代码补全工具,而是深度理解技术设计文档的编码伙伴——它能读设计文档生成代码骨架,能作为第一个Reviewer审查PR,能嵌入CI/CD流水线做质量门禁。
1. 开篇:现有编码工具不理解设计文档
Copilot、Cursor、Claude Code——这些编码工具已经很好了,但它们有一个共同的盲区:它们只理解代码上下文,不理解设计文档。
一个真实场景:RD写完技术设计文档,里面有完整的接口定义、数据模型、业务流程。打开IDE开始编码,Copilot的补全基于当前文件的上下文——它不知道设计文档里定义了什么接口、什么数据模型、什么流程。
结果是:RD一边看着设计文档,一边手动把文档里的接口定义、数据模型翻译成代码。这个翻译过程是机械的、重复的、容易出错的。如果设计文档改了,代码不一定跟着改。如果代码改了,设计文档不一定同步。
研发执行Agent要解决的,就是从设计文档到代码的最后一公里:
- 基于设计文档生成代码骨架
——不是基于当前文件上下文补全,而是读取设计文档中的接口定义、数据模型、业务流程,生成代码骨架和核心实现 - PR审查
——Agent作为第一个Reviewer,检查代码与设计文档的一致性、代码规范、潜在Bug、安全风险 - 质量门禁
——在CI/CD流水线中嵌入Agent质量检查节点,检查单测覆盖率、集成测试完整性、日志埋点完备性
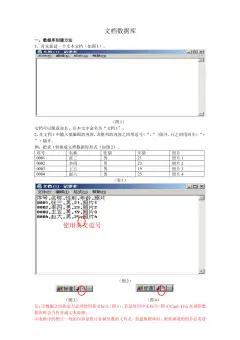
1.1 研发执行Agent的三大能力
1.2 和现有编码工具的定位差异
定位关系:两者互补,不是替代。Copilot负责行级补全,研发执行Agent负责设计文档到代码骨架的翻译、PR审查和CI门禁。RD在日常编码中两者都用。
2. 设计文档驱动代码生成
2.1 代码生成架构
from dataclasses import dataclassfrom typing importOptionalfrom enum import EnumclassGenerateTarget(Enum):"""生成目标类型""" INTERFACE = "interface"# 接口定义 MODEL = "model"# 数据模型/Entity SERVICE = "service"# Service层 REPOSITORY = "repository"# 数据访问层 CONTROLLER = "controller"# Controller层 CONFIG = "config"# 配置类 TEST = "test"# 测试类 SKELETON = "skeleton"# 完整骨架@dataclassclassGeneratedCode:"""生成的代码""" target_type: GenerateTarget file_path: str class_name: str code: str language: str imports: list[str] dependencies: list[str] # 依赖的其他类 test_code: Optional[str] # 对应的测试代码 design_doc_ref: str# 对应设计文档的章节classCodeGenerator:"""设计文档驱动代码生成器"""def__init__(self, llm_client, code_search, design_doc: str):self.llm = llm_clientself.code_search = code_searchself.design_doc = design_docself._parsed_doc = Nonedefgenerate(self, target: GenerateTarget) -> list[GeneratedCode]:"""根据目标类型生成代码""" doc = self._get_parsed_doc() generators = { GenerateTarget.MODEL: self._gen_models, GenerateTarget.INTERFACE: self._gen_interfaces, GenerateTarget.REPOSITORY: self._gen_repositories, GenerateTarget.SERVICE: self._gen_services, GenerateTarget.CONTROLLER: self._gen_controllers, GenerateTarget.SKELETON: self._gen_skeleton, } gen_func = generators.get(target)ifnot gen_func:return []return gen_func(doc)def_get_parsed_doc(self) -> dict:"""解析设计文档为结构化数据"""ifself._parsed_doc:returnself._parsed_doc prompt = f""" 解析以下技术设计文档,提取结构化信息:{self.design_doc[:5000]} 输出JSON格式: {{ "project_info": {{ "name": "项目名", "language": "java/python/go", "framework": "spring boot/fastapi/gin", "base_package": "com.xxx.xxx" }}, "data_models": [ {{ "name": "类名", "table_name": "表名", "fields": [ {{"name":"字段名","type":"类型","nullable":true,"comment":"注释"}} ], "indexes": ["索引字段"], "relations": ["关联的表"] }} ], "api_endpoints": [ {{ "method": "GET/POST/PUT/DELETE", "path": "/api/xxx", "description": "描述", "request_params": [{{"name":"","type":"","required":true}}], "response": "返回类型", "auth_required": true }} ], "business_flows": [ {{ "name": "流程名", "steps": ["步骤1","步骤2"], "exception_handling": "异常处理方式" }} ] }} """ result = self.llm.chat(prompt)import jsonself._parsed_doc = json.loads(result)returnself._parsed_docdef_gen_models(self, doc: dict) -> list[GeneratedCode]:"""生成数据模型代码""" models = doc.get("data_models", []) project = doc.get("project_info", {}) results = []for model in models: prompt = self._build_model_prompt(model, project) code = self.llm.chat(prompt) test_code = self._gen_model_test(model, project, code) results.append(GeneratedCode( target_type=GenerateTarget.MODEL, file_path=self._get_model_path(model["name"], project), class_name=model["name"], code=code, language=project.get("language", "java"), imports=[], dependencies=[], test_code=test_code, design_doc_ref=f"数据模型: {model['name']}", ))return resultsdef_build_model_prompt(self, model: dict, project: dict) -> str:"""构建数据模型生成Prompt""" lang = project.get("language", "java") framework = project.get("framework", "spring boot") pkg = project.get("base_package", "com.example") fields_str = "\n".join(f" - {f['name']}: {f['type']} "f"({'可空'if f.get('nullable') else'非空'}) "f"{f.get('comment', '')}"for f in model.get("fields", []) ) indexes_str = ", ".join(model.get("indexes", [])) relations_str = ", ".join(model.get("relations", []))returnf""" 生成{lang}数据模型类。 项目信息: - 语言:{lang} - 框架:{framework} - 包名:{pkg} 模型信息: - 类名:{model['name']} - 表名:{model.get('table_name', model['name'].lower())} - 字段:{fields_str} - 索引:{indexes_str} - 关联:{relations_str} 要求: 1. 使用{framework}的标准注解 2. 包含所有字段的getter/setter(或Lombok注解) 3. 添加字段注释 4. 包含表名映射注解 5. 生成完整的import语句 """def_gen_model_test( self, model: dict, project: dict, model_code: str) -> str:"""生成数据模型的测试代码""" lang = project.get("language", "java") prompt = f""" 为以下{lang}数据模型生成单元测试: 模型名:{model['name']} 模型代码:{model_code[:2000]} 测试要求: 1. 测试所有字段的getter/setter 2. 测试equals和hashCode(如适用) 3. 测试边界值(null/空字符串/最大长度) 4. 使用JUnit 5 + AssertJ """returnself.llm.chat(prompt)def_gen_interfaces(self, doc: dict) -> list[GeneratedCode]:"""生成接口定义代码""" endpoints = doc.get("api_endpoints", []) project = doc.get("project_info", {})# 按模块分组接口 modules = {}for ep in endpoints: module = self._extract_module(ep["path"])if module notin modules: modules[module] = [] modules[module].append(ep) results = []for module, eps in modules.items(): class_name = f"{module.capitalize()}Controller" prompt = self._build_controller_prompt(eps, project, class_name) code = self.llm.chat(prompt) test_code = self._gen_controller_test(eps, project, code) results.append(GeneratedCode( target_type=GenerateTarget.CONTROLLER, file_path=self._get_controller_path(class_name, project), class_name=class_name, code=code, language=project.get("language", "java"), imports=[], dependencies=[], test_code=test_code, design_doc_ref=f"接口设计: {module}", ))return resultsdef_build_controller_prompt( self, endpoints: list, project: dict, class_name: str) -> str:"""构建Controller生成Prompt""" lang = project.get("language", "java") framework = project.get("framework", "spring boot") pkg = project.get("base_package", "com.example") eps_str = "\n".join(f" - {ep['method']}{ep['path']}: {ep.get('description','')}\n"f" 参数: {ep.get('request_params', [])}\n"f" 返回: {ep.get('response', '')}\n"f" 鉴权: {'是'if ep.get('auth_required') else'否'}"for ep in endpoints )returnf""" 生成{lang}{framework} Controller类。 项目信息: - 语言:{lang} - 框架:{framework} - 包名:{pkg} 类名:{class_name} 接口列表:{eps_str} 要求: 1. 使用{framework}的标准注解(@RestController @RequestMapping等) 2. 每个接口包含参数校验注解 3. 统一返回格式(Result<T>) 4. 异常处理注解 5. 完整的import语句 6. 每个方法添加JavaDoc注释 7. 日志埋点(入参+出参+耗时) """def_gen_controller_test( self, endpoints: list, project: dict, controller_code: str) -> str:"""生成Controller测试""" prompt = f""" 为以下Controller生成集成测试:{controller_code[:3000]} 接口列表:{endpoints} 测试要求: 1. 使用 MockMvc 2. 每个接口测试正常流程和异常流程 3. 测试参数校验 4. 测试鉴权 """returnself.llm.chat(prompt)def_gen_services(self, doc: dict) -> list[GeneratedCode]:"""生成Service层代码""" flows = doc.get("business_flows", []) endpoints = doc.get("api_endpoints", []) project = doc.get("project_info", {})# 按模块分组 modules = set()for ep in endpoints: modules.add(self._extract_module(ep["path"])) results = []for module in modules: class_name = f"{module.capitalize()}Service"# 收集该模块的流程 module_flows = [ f for f in flowsif module.lower() in f.get("name", "").lower() ] prompt = f""" 生成{project.get('language','java')} Service类。 项目:{project.get('framework','spring boot')} 包名:{project.get('base_package','com.example')} 类名:{class_name} 相关接口:{[ep for ep in endpoints if module in ep['path']]} 业务流程:{module_flows} 要求: 1. Service接口+实现类 2. 事务注解 3. 日志埋点 4. 异常处理 5. 依赖注入Repository """ code = self.llm.chat(prompt) results.append(GeneratedCode( target_type=GenerateTarget.SERVICE, file_path=self._get_service_path(class_name, project), class_name=class_name, code=code, language=project.get("language", "java"), imports=[], dependencies=[], test_code=None, design_doc_ref=f"业务流程: {module}", ))return resultsdef_gen_repositories(self, doc: dict) -> list[GeneratedCode]:"""生成数据访问层代码""" models = doc.get("data_models", []) project = doc.get("project_info", {}) results = []for model in models: class_name = f"{model['name']}Repository" prompt = f""" 生成{project.get('language','java')} Repository接口。 框架:{project.get('framework','spring boot')} 包名:{project.get('base_package','com.example')} 实体:{model['name']} 表名:{model.get('table_name', model['name'].lower())} 要求: 1. 继承JpaRepository(或MyBatis Mapper) 2. 包含基本CRUD 3. 根据索引字段添加查询方法 4. 自定义查询使用@Query注解 """ code = self.llm.chat(prompt) results.append(GeneratedCode( target_type=GenerateTarget.REPOSITORY, file_path=self._get_repo_path(class_name, project), class_name=class_name, code=code, language=project.get("language", "java"), imports=[], dependencies=[model["name"]], test_code=None, design_doc_ref=f"数据访问: {model['name']}", ))return resultsdef_gen_skeleton(self, doc: dict) -> list[GeneratedCode]:"""生成完整项目骨架""" all_code = [] all_code.extend(self._gen_models(doc)) all_code.extend(self._gen_repositories(doc)) all_code.extend(self._gen_services(doc)) all_code.extend(self._gen_interfaces(doc))return all_codedef_extract_module(self, path: str) -> str:"""从API路径提取模块名""" parts = path.strip("/").split("/")return parts[0] if parts else"default"def_get_model_path(self, name: str, project: dict) -> str: pkg = project.get("base_package", "com.example").replace(".", "/")returnf"src/main/java/{pkg}/model/{name}.java"def_get_controller_path(self, name: str, project: dict) -> str: pkg = project.get("base_package", "com.example").replace(".", "/")returnf"src/main/java/{pkg}/controller/{name}.java"def_get_service_path(self, name: str, project: dict) -> str: pkg = project.get("base_package", "com.example").replace(".", "/")returnf"src/main/java/{pkg}/service/{name}.java"def_get_repo_path(self, name: str, project: dict) -> str: pkg = project.get("base_package", "com.example").replace(".", "/")returnf"src/main/java/{pkg}/repository/{name}.java"2.2 代码生成示例
以"支付对账功能"为例,Agent基于设计文档生成的Model和Controller代码:
// === 生成的数据模型 ===package com.example.payment.model;import javax.persistence.*;import lombok.Data;import java.time.LocalDateTime;/** * 对账结果表 * 对应表: reconciliation_result */@Data@Entity@Table(name = "reconciliation_result", indexes = { @Index(name = "idx_batch_id", columnList = "batch_id"), @Index(name = "idx_channel", columnList = "channel"), @Index(name = "idx_status", columnList = "status"), @Index(name = "idx_created_at", columnList = "created_at") })publicclassReconciliationResult {@Id@GeneratedValue(strategy = GenerationType.IDENTITY)private Long id;/** 对账批次ID */@Column(name = "batch_id", nullable = false, length = 64)private String batchId;/** 支付通道: ALIPAY/WXPAY/UNIONPAY */@Column(name = "channel", nullable = false, length = 20)private String channel;/** 对账模式: T0/T1 */@Column(name = "reconcile_mode", nullable = false, length = 4)private String reconcileMode;/** 本方订单号 */@Column(name = "local_order_id", length = 64)private String localOrderId;/** 通道订单号 */@Column(name = "channel_order_id", length = 64)private String channelOrderId;/** 对账状态: MATCHED/MISMATCH/LOCAL_ONLY/CHANNEL_ONLY */@Column(name = "status", nullable = false, length = 20)private String status;/** 差异金额(分) */@Column(name = "diff_amount")private Long diffAmount;/** 差异原因 */@Column(name = "diff_reason", length = 500)private String diffReason;/** 处理状态: PENDING/AUTO_RESOLVED/MANUAL_RESOLVED */@Column(name = "resolution_status", length = 20)private String resolutionStatus;@Column(name = "created_at", nullable = false)private LocalDateTime createdAt;@Column(name = "updated_at")private LocalDateTime updatedAt;}// === 生成的Controller ===package com.example.payment.controller;import com.example.payment.model.ReconciliationResult;import com.example.payment.service.ReconciliationService;import io.swagger.annotations.Api;import io.swagger.annotations.ApiOperation;import lombok.RequiredArgsConstructor;import lombok.extern.slf4j.Slf4j;import org.springframework.web.bind.annotation.*;import javax.validation.Valid;import java.util.List;/** * 对账接口 */@Slf4j@RestController@RequestMapping("/api/reconciliation")@RequiredArgsConstructor@Api(tags = "对账管理")publicclassReconciliationController {privatefinal ReconciliationService reconciliationService;/** * 触发对账 */@PostMapping("/trigger")@ApiOperation("手动触发对账")public Result<String> triggerReconciliation(@Valid@RequestBody TriggerRequest request) { log.info("触发对账: channel={}, mode={}", request.getChannel(), request.getMode());StringbatchId= reconciliationService.trigger( request.getChannel(), request.getMode()); log.info("对账触发成功: batchId={}", batchId);return Result.success(batchId); }/** * 查询对账结果 */@GetMapping("/results")@ApiOperation("查询对账结果")public Result<List<ReconciliationResult>> getResults(@RequestParam String batchId,@RequestParam(required = false) String status) { log.info("查询对账结果: batchId={}, status={}", batchId, status); List<ReconciliationResult> results = reconciliationService.getResults(batchId, status);return Result.success(results); }/** * 查询差异列表 */@GetMapping("/diffs")@ApiOperation("查询差异列表")public Result<List<ReconciliationResult>> getDiffs(@RequestParam String batchId,@RequestParam(defaultValue = "1")int page,@RequestParam(defaultValue = "20")int size) { log.info("查询差异列表: batchId={}, page={}, size={}", batchId, page, size); List<ReconciliationResult> diffs = reconciliationService.getDiffs(batchId, page, size);return Result.success(diffs); }/** * 处理差异 */@PostMapping("/diffs/{id}/resolve")@ApiOperation("处理差异")public Result<Void> resolveDiff(@PathVariable Long id,@Valid@RequestBody ResolveRequest request) { log.info("处理差异: id={}, action={}", id, request.getAction()); reconciliationService.resolveDiff(id, request);return Result.success(null); }}2.3 代码生成的质量控制
classCodeQualityValidator:"""代码质量验证器"""def__init__(self, llm_client):self.llm = llm_clientdefvalidate( self, generated: GeneratedCode, design_doc_section: str) -> dict:"""验证生成的代码质量""" issues = []# 1. 设计文档一致性检查 consistency = self._check_design_consistency( generated, design_doc_section ) issues.extend(consistency)# 2. 代码规范检查 convention = self._check_convention(generated) issues.extend(convention)# 3. 编译可行性检查 compilable = self._check_compilable(generated) issues.extend(compilable)return {"total_issues": len(issues),"issues": issues,"quality_score": self._calc_score(issues), }def_check_design_consistency( self, code: GeneratedCode, doc_section: str) -> list[dict]:"""检查代码与设计文档的一致性""" prompt = f""" 检查以下代码是否与设计文档一致: 设计文档章节:{doc_section[:1000]} 生成的代码:{code.code[:2000]} 检查: 1. 字段名是否与设计文档一致 2. 字段类型是否匹配 3. 接口路径是否一致 4. 是否遗漏了设计文档中的字段/接口 输出JSON数组:[{{"type":"","description":""}}],无问题返回[]。 """ result = self.llm.chat(prompt)import jsontry:return json.loads(result)except json.JSONDecodeError:return []def_check_convention(self, code: GeneratedCode) -> list[dict]:"""检查代码规范""" issues = []# 检查是否有日志if code.target_type in [ GenerateTarget.CONTROLLER, GenerateTarget.SERVICE ]:if"log."notin code.code and"logger."notin code.code: issues.append({"type": "convention","description": "缺少日志埋点", })# 检查是否有注释if"//"notin code.code and"/*"notin code.code: issues.append({"type": "convention","description": "缺少代码注释", })# 检查异常处理if code.target_type == GenerateTarget.SERVICE:if"try"notin code.code and"throw"notin code.code: issues.append({"type": "convention","description": "Service层缺少异常处理", })return issuesdef_check_compilable(self, code: GeneratedCode) -> list[dict]:"""检查编译可行性(简化版)""" issues = []# 检查括号匹配 open_braces = code.code.count("{") close_braces = code.code.count("}")if open_braces != close_braces: issues.append({"type": "syntax","description": f"大括号不匹配: {{={open_braces}, }}={close_braces}", })# 检查分号(Java)if code.language == "java": lines = code.code.split("\n")for i, line inenumerate(lines, 1): stripped = line.strip()if (stripped andnot stripped.endswith(";") andnot stripped.endswith("{") andnot stripped.endswith("}")andnot stripped.endswith(",")andnot stripped.startswith("//")andnot stripped.startswith("*")andnot stripped.startswith("/*")andnot stripped.startswith("package")andnot stripped.startswith("import")): issues.append({"type": "syntax","description": f"第{i}行可能缺少分号: {stripped[:50]}", })return issuesdef_calc_score(self, issues: list[dict]) -> float: score = 10.0for issue in issues:if issue.get("type") == "syntax": score -= 2.0elif issue.get("type") == "convention": score -= 0.5elif issue.get("type") == "design_consistency": score -= 1.0returnmax(score, 0.0)3. PR智能审查
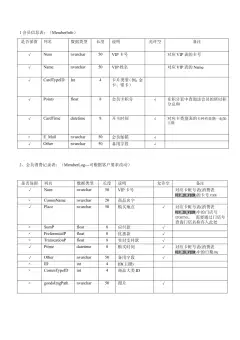
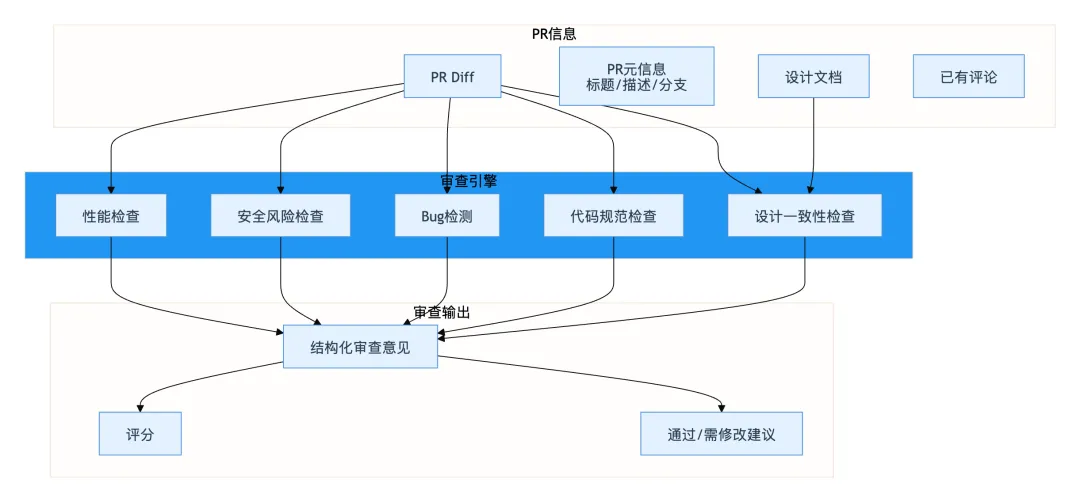
3.1 审查引擎架构
3.2 PR审查引擎
@dataclassclassReviewComment:"""审查意见""" file_path: str line_number: int severity: str# critical / major / minor / nitpick category: str# 设计一致性/规范/Bug/安全/性能 comment: str suggestion: str# 修改建议(含代码) inline: bool# 是否行内评论@dataclassclassPRReviewResult:"""PR审查结果""" overall_score: float comments: list[ReviewComment] summary: str recommendation: str# approve / request_changes / comment checked_files: int checked_lines: intclassPRReviewEngine:"""PR审查引擎"""def__init__(self, llm_client, code_search, design_doc: str):self.llm = llm_clientself.code_search = code_searchself.design_doc = design_docself.reviewers = [ DesignConsistencyReviewer(llm_client, design_doc), CodeConventionReviewer(llm_client), BugDetectionReviewer(llm_client), SecurityReviewer(llm_client), PerformanceReviewer(llm_client), ]defreview( self, pr_diff: str, pr_metadata: dict, existing_comments: list = None,) -> PRReviewResult:"""执行PR审查"""# 解析diff为文件变更 file_changes = self._parse_diff(pr_diff) all_comments = []for reviewer inself.reviewers: comments = reviewer.review(file_changes, pr_metadata) all_comments.extend(comments)# 去重 all_comments = self._deduplicate(all_comments)# 生成总结 summary = self._generate_summary(all_comments, pr_metadata)# 计算评分和建议 score = self._calc_score(all_comments) recommendation = self._get_recommendation(all_comments, score) checked_files = len(file_changes) checked_lines = sum(len(f.get("added_lines", [])) for f in file_changes )return PRReviewResult( overall_score=score, comments=all_comments, summary=summary, recommendation=recommendation, checked_files=checked_files, checked_lines=checked_lines, )def_parse_diff(self, diff: str) -> list[dict]:"""解析diff为文件变更列表"""import re files = [] current_file = Nonefor line in diff.split("\n"):if line.startswith("diff --git"):if current_file: files.append(current_file) current_file = {"path": "", "added_lines": [], "removed_lines": []}match = re.search(r'b/(.+)$', line)ifmatch: current_file["path"] = match.group(1)elif line.startswith("+++") or line.startswith("---"):continueelif line.startswith("+") andnot line.startswith("+++"):if current_file: current_file["added_lines"].append(line[1:])elif line.startswith("-") andnot line.startswith("---"):if current_file: current_file["removed_lines"].append(line[1:])if current_file: files.append(current_file)return filesdef_deduplicate( self, comments: list[ReviewComment]) -> list[ReviewComment]:"""去重""" seen = set() unique = []for c in comments: key = f"{c.file_path}:{c.line_number}:{c.category}"if key notin seen: seen.add(key) unique.append(c)return uniquedef_generate_summary( self, comments: list[ReviewComment], metadata: dict) -> str:"""生成审查总结""" critical = sum(1for c in comments if c.severity == "critical") major = sum(1for c in comments if c.severity == "major") minor = sum(1for c in comments if c.severity == "minor") prompt = f""" 生成PR审查总结。 PR标题: {metadata.get('title', '')} PR描述: {metadata.get('description', '')} 审查结果: - Critical: {critical} - Major: {major} - Minor: {minor} 关键问题:{self._format_top_issues(comments[:5])} 生成200字以内的审查总结。 """returnself.llm.chat(prompt)def_format_top_issues( self, comments: list[ReviewComment]) -> str:return"\n".join(f"- [{c.severity}] {c.file_path}:{c.line_number}{c.comment}"for c in comments )def_calc_score(self, comments: list[ReviewComment]) -> float: score = 10.0for c in comments:if c.severity == "critical": score -= 2.0elif c.severity == "major": score -= 1.0elif c.severity == "minor": score -= 0.3elif c.severity == "nitpick": score -= 0.1returnmax(score, 0.0)def_get_recommendation( self, comments: list[ReviewComment], score: float) -> str: critical = sum(1for c in comments if c.severity == "critical") major = sum(1for c in comments if c.severity == "major")if critical > 0:return"request_changes"elif major > 2or score < 6.0:return"request_changes"elif major > 0or score < 8.0:return"comment"else:return"approve"3.3 设计一致性审查器
classDesignConsistencyReviewer:"""设计一致性审查器——检查代码是否与设计文档一致"""def__init__(self, llm_client, design_doc: str):self.llm = llm_clientself.design_doc = design_docdefreview( self, file_changes: list[dict], pr_metadata: dict) -> list[ReviewComment]: comments = []for change in file_changes: file_path = change["path"] added = "\n".join(change["added_lines"])ifnot added.strip():continue# 检查与设计文档的一致性 prompt = f""" 检查以下代码变更是否与技术设计文档一致。 设计文档:{self.design_doc[:3000]} 文件: {file_path} 新增代码:{added[:2000]} 检查维度: 1. 接口路径是否与设计文档一致 2. 字段名和类型是否匹配 3. 是否遗漏了设计文档中定义的字段/接口 4. 业务逻辑是否与流程设计一致 输出JSON数组: [{{ "line": 0, "severity": "major/minor", "comment": "问题描述", "suggestion": "修改建议" }}] 无问题返回[]。 """ result = self.llm.chat(prompt)import jsontry: issues = json.loads(result)for issue in issues: comments.append(ReviewComment( file_path=file_path, line_number=issue.get("line", 0), severity=issue.get("severity", "minor"), category="设计一致性", comment=issue.get("comment", ""), suggestion=issue.get("suggestion", ""), inline=True, ))except (json.JSONDecodeError, KeyError):passreturn commentsclassCodeConventionReviewer:"""代码规范审查器"""def__init__(self, llm_client):self.llm = llm_clientdefreview(self, file_changes: list, metadata: dict) -> list[ReviewComment]: comments = []for change in file_changes: file_path = change["path"]for i, line inenumerate(change["added_lines"], 1):# 检查命名规范if"class "in line: class_name = line.split("class ")[1].split(" ")[0].split("{")[0].strip()if class_name andnot class_name[0].isupper(): comments.append(ReviewComment( file_path=file_path, line_number=i, severity="minor", category="规范", comment=f"类名{class_name}应大写开头", suggestion=f"改为{class_name.capitalize()}", inline=True, ))# 检查魔法数字import re numbers = re.findall(r'\b(\d{3,})\b', line)for num in numbers:if num notin ["200", "404", "500", "301", "302"]: comments.append(ReviewComment( file_path=file_path, line_number=i, severity="nitpick", category="规范", comment=f"魔法数字{num},建议提取为常量", suggestion="提取为命名常量", inline=True, ))# 检查TODO/FIXMEif"TODO"in line or"FIXME"in line: comments.append(ReviewComment( file_path=file_path, line_number=i, severity="minor", category="规范", comment="包含TODO/FIXME,上线前需处理", suggestion="处理或创建Issue跟踪", inline=True, ))return commentsclassBugDetectionReviewer:"""Bug检测审查器"""def__init__(self, llm_client):self.llm = llm_clientdefreview(self, file_changes: list, metadata: dict) -> list[ReviewComment]: comments = []for change in file_changes: file_path = change["path"] added = "\n".join(change["added_lines"])ifnot added.strip():continue prompt = f""" 检查以下代码变更中的潜在Bug: 文件: {file_path} 代码:{added[:2000]} 检查: 1. 空指针风险 2. 并发安全问题 3. 资源泄漏(未关闭的流/连接) 4. 数组越界 5. 类型转换异常 6. 逻辑错误(条件判断/循环) 7. 事务问题 输出JSON数组:[{{"line":0,"severity":"critical/major/minor","comment":"","suggestion":""}}] 无问题返回[]。 """ result = self.llm.chat(prompt)import jsontry: issues = json.loads(result)for issue in issues: comments.append(ReviewComment( file_path=file_path, line_number=issue.get("line", 0), severity=issue.get("severity", "minor"), category="Bug", comment=issue.get("comment", ""), suggestion=issue.get("suggestion", ""), inline=True, ))except (json.JSONDecodeError, KeyError):passreturn commentsclassSecurityReviewer:"""安全风险审查器"""def__init__(self, llm_client):self.llm = llm_clientdefreview(self, file_changes: list, metadata: dict) -> list[ReviewComment]: comments = []for change in file_changes: file_path = change["path"]for i, line inenumerate(change["added_lines"], 1):# SQL注入风险if"String sql"in line and"+"in line: comments.append(ReviewComment( file_path=file_path, line_number=i, severity="critical", category="安全", comment="可能的SQL注入:字符串拼接SQL", suggestion="使用参数化查询或PreparedStatement", inline=True, ))# 敏感信息硬编码import reif re.search(r'(password|secret|key|token)\s*=\s*["\']', line, re.I): comments.append(ReviewComment( file_path=file_path, line_number=i, severity="critical", category="安全", comment="敏感信息硬编码", suggestion="使用配置中心或环境变量", inline=True, ))# XSS风险if"<script"in line.lower(): comments.append(ReviewComment( file_path=file_path, line_number=i, severity="major", category="安全", comment="可能的XSS风险", suggestion="对用户输入进行转义", inline=True, ))return commentsclassPerformanceReviewer:"""性能审查器"""def__init__(self, llm_client):self.llm = llm_clientdefreview(self, file_changes: list, metadata: dict) -> list[ReviewComment]: comments = []for change in file_changes: file_path = change["path"]for i, line inenumerate(change["added_lines"], 1):# N+1查询风险if".forEach("in line and".findById("in line: comments.append(ReviewComment( file_path=file_path, line_number=i, severity="major", category="性能", comment="可能的N+1查询:循环内查数据库", suggestion="使用批量查询", inline=True, ))# 循环内创建对象if ("for "in line or".stream()"in line) and"new "in line: comments.append(ReviewComment( file_path=file_path, line_number=i, severity="minor", category="性能", comment="循环内创建对象,考虑复用", suggestion="提取到循环外", inline=True, ))# 大列表未分页if".findAll()"in line: comments.append(ReviewComment( file_path=file_path, line_number=i, severity="minor", category="性能", comment="全量查询风险,数据量大时性能差", suggestion="使用分页查询", inline=True, ))return comments3.4 PR审查报告示例
# PR审查报告## 审查摘要| 指标 | 值 ||------|-----|| 评分 | 7.5/10 || 审查文件 | 8 || 审查行数 | 245 || Critical | 0 || Major | 2 || Minor | 5 || Nitpick | 3 |**建议**: request_changes——存在2个主要问题需修复## 审查总结PR实现了对账功能的Controller、Service和Repository层,整体架构与设计文档一致。主要问题:1)ReconciliationService的compare方法缺少事务注解,可能导致差异写入时的数据不一致;2)通道适配器未做超时处理,通道响应慢时会阻塞对账主流程。建议修复后合并。## 审查意见| # | 严重度 | 文件 | 行 | 类别 | 描述 | 建议 ||---|--------|------|----|------|------|------|| 1 | major | ReconciliationService.java | 45 | Bug | compare方法缺少@Transactional | 添加@Transactional注解 || 2 | major | AlipayAdapter.java | 32 | 性能 | 未设置HTTP超时 | 添加5s超时配置 || 3 | minor | ReconciliationController.java | 28 | 设计一致性 | 接口路径为/trigger但设计文档为/reconcile | 统一为/reconcile || 4 | minor | ReconciliationResult.java | 15 | 规范 | 魔法数字200 | 提取为常量MAX_BATCH_SIZE || 5 | minor | DiffProcessor.java | 67 | Bug | 循环内IO操作 | 批量处理 || 6 | minor | ReconciliationService.java | 89 | 规范 | TODO注释 | 创建Issue跟踪 || 7 | nitpick | ReconciliationResult.java | 30 | 规范 | 字段命名diffAmount不一致 | 改为differenceAmount |4. CI/CD质量门禁
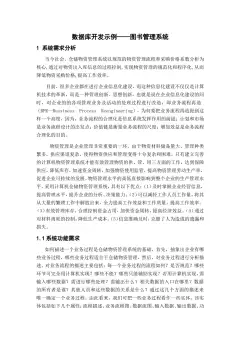
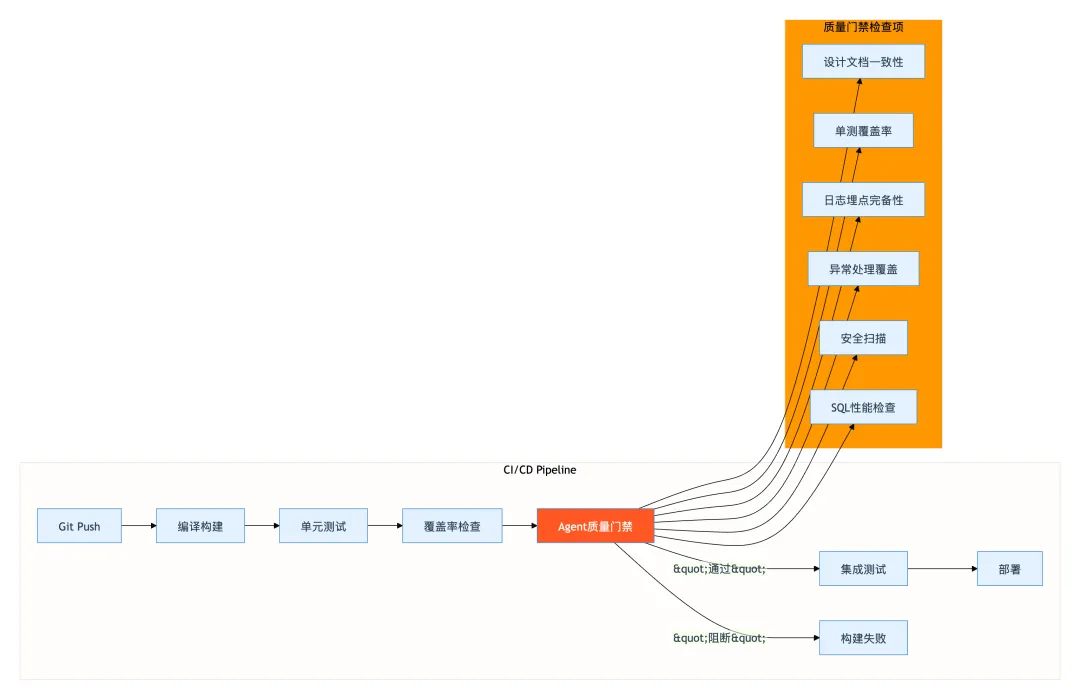
4.1 质量门禁架构
4.2 质量门禁引擎
@dataclassclassGateResult:"""门禁检查结果""" gate_name: str passed: bool score: float details: str blocking: bool# 是否阻断构建classQualityGateEngine:"""CI/CD质量门禁引擎"""def__init__(self, llm_client, design_doc: str):self.llm = llm_clientself.design_doc = design_docself.gates = [ DesignConsistencyGate(design_doc), TestCoverageGate(), LoggingGate(), ExceptionHandlingGate(), SecurityScanGate(), SQLPerformanceGate(), ]defrun_gates( self, repo_path: str, changed_files: list[str], test_results: dict,) -> list[GateResult]:"""运行所有质量门禁""" results = []for gate inself.gates: result = gate.check(repo_path, changed_files, test_results) results.append(result)# 阻断性门禁失败,立即返回if result.blocking andnot result.passed:breakreturn resultsdefgenerate_report( self, results: list[GateResult]) -> str:"""生成质量门禁报告""" all_passed = all(r.passed for r in results) report = "# 质量门禁检查报告\n\n" report += f"**总体结果**: {'✅ 通过'if all_passed else'❌ 阻断'}\n\n" report += "| 门禁 | 状态 | 评分 | 详情 |\n" report += "|------|------|------|------|\n"for r in results: status = "✅"if r.passed else"❌" report += f"| {r.gate_name} | {status} | {r.score:.1f} | {r.details[:50]} |\n"# 阻断项详情 blocking = [r for r in results ifnot r.passed and r.blocking]if blocking: report += "\n## 阻断项详情\n\n"for r in blocking: report += f"### {r.gate_name}\n{r.details}\n\n"return reportclassDesignConsistencyGate:"""设计文档一致性门禁"""def__init__(self, design_doc: str):self.design_doc = design_docdefcheck(self, repo_path, changed_files, test_results) -> GateResult:# 简化检查:检查代码中是否包含设计文档定义的接口路径import os missing = []for file_path in changed_files: full_path = os.path.join(repo_path, file_path)ifnot os.path.exists(full_path):continuewithopen(full_path, 'r') as f: content = f.read()# 检查设计文档中的接口是否在代码中实现import re endpoints = re.findall(r'(GET|POST|PUT|DELETE)\s+(/\S+)', self.design_doc )for method, path in endpoints:if path notin content: missing.append(f"{method}{path}")if missing:return GateResult( gate_name="设计文档一致性", passed=False, score=5.0, details=f"缺少接口: {', '.join(missing[:3])}", blocking=True, )return GateResult( gate_name="设计文档一致性", passed=True, score=10.0, details="所有设计文档接口已实现", blocking=True, )classTestCoverageGate:"""测试覆盖率门禁""" MIN_COVERAGE = 0.70# 最低70%覆盖率defcheck(self, repo_path, changed_files, test_results) -> GateResult: coverage = test_results.get("coverage", 0)if coverage < self.MIN_COVERAGE:return GateResult( gate_name="测试覆盖率", passed=False, score=coverage * 10, details=f"覆盖率{coverage*100:.1f}%低于阈值{self.MIN_COVERAGE*100:.0f}%", blocking=True, )return GateResult( gate_name="测试覆盖率", passed=True, score=coverage * 10, details=f"覆盖率{coverage*100:.1f}%", blocking=True, )classLoggingGate:"""日志埋点门禁"""defcheck(self, repo_path, changed_files, test_results) -> GateResult:import os missing_log = []for file_path in changed_files:if"Controller"notin file_path and"Service"notin file_path:continue full_path = os.path.join(repo_path, file_path)ifnot os.path.exists(full_path):continuewithopen(full_path, 'r') as f: content = f.read()# 检查每个public方法是否有日志import re methods = re.findall(r'public\s+\w+\s+(\w+)\s*\(', content )for method in methods:if method in ['getter', 'setter', 'toString']:continue# 简化检查:方法前后是否有log调用if content.count("log.") < len(methods): missing_log.append(f"{file_path}::{method}")if missing_log:return GateResult( gate_name="日志埋点", passed=True, # 非阻断 score=6.0, details=f"部分方法缺少日志: {', '.join(missing_log[:3])}", blocking=False, )return GateResult( gate_name="日志埋点", passed=True, score=10.0, details="日志埋点完备", blocking=False, )classExceptionHandlingGate:"""异常处理门禁"""defcheck(self, repo_path, changed_files, test_results) -> GateResult:import os issues = []for file_path in changed_files:if"Service"notin file_path:continue full_path = os.path.join(repo_path, file_path)ifnot os.path.exists(full_path):continuewithopen(full_path, 'r') as f: content = f.read()# 检查是否有裸catchif"catch (Exception e)"in content and"throw"notin content: issues.append(f"{file_path}: 裸catch未抛出异常")# 检查是否有e.printStackTrace()if"printStackTrace"in content: issues.append(f"{file_path}: 使用printStackTrace而非日志")if issues:return GateResult( gate_name="异常处理", passed=False, score=5.0, details="; ".join(issues[:3]), blocking=False, )return GateResult( gate_name="异常处理", passed=True, score=10.0, details="异常处理规范", blocking=False, )classSecurityScanGate:"""安全扫描门禁"""defcheck(self, repo_path, changed_files, test_results) -> GateResult:import os, re issues = []for file_path in changed_files: full_path = os.path.join(repo_path, file_path)ifnot os.path.exists(full_path):continuewithopen(full_path, 'r') as f: content = f.read()# SQL注入if re.search(r'String\s+sql\s*=.*\+', content): issues.append(f"{file_path}: SQL拼接风险")# 硬编码密码if re.search(r'password\s*=\s*["\']', content, re.I): issues.append(f"{file_path}: 硬编码密码")# 不安全的随机数if"Math.random()"in content and"token"in content.lower(): issues.append(f"{file_path}: 使用Math.random生成token")if issues:return GateResult( gate_name="安全扫描", passed=False, score=0.0, details="; ".join(issues), blocking=True, )return GateResult( gate_name="安全扫描", passed=True, score=10.0, details="无安全风险", blocking=True, )classSQLPerformanceGate:"""SQL性能门禁"""defcheck(self, repo_path, changed_files, test_results) -> GateResult:import os, re issues = []for file_path in changed_files:ifnot file_path.endswith((".java", ".xml")):continue full_path = os.path.join(repo_path, file_path)ifnot os.path.exists(full_path):continuewithopen(full_path, 'r') as f: content = f.read()# 检查SELECT *if re.search(r'SELECT\s+\*', content, re.I): issues.append(f"{file_path}: SELECT * 查询")# 检查无LIMIT的查询if re.search(r'findAll\(\)', content): issues.append(f"{file_path}: findAll()无分页")# 检查无索引的WHEREif re.search(r'WHERE\s+\w+\s*LIKE\s+[\'\"]%', content, re.I): issues.append(f"{file_path}: LIKE前缀模糊查询无法走索引")if issues:return GateResult( gate_name="SQL性能", passed=True, score=5.0, details="; ".join(issues[:3]), blocking=False, )return GateResult( gate_name="SQL性能", passed=True, score=10.0, details="SQL性能检查通过", blocking=False, )4.3 门禁报告示例
# 质量门禁检查报告**总体结果**: ❌ 阻断| 门禁 | 状态 | 评分 | 详情 ||------|------|------|------|| 设计文档一致性 | ✅ | 10.0 | 所有设计文档接口已实现 || 测试覆盖率 | ❌ | 5.2 | 覆盖率52.0%低于阈值70% || 日志埋点 | ✅ | 6.0 | 部分方法缺少日志 || 异常处理 | ✅ | 10.0 | 异常处理规范 || 安全扫描 | ✅ | 10.0 | 无安全风险 || SQL性能 | ✅ | 5.0 | SELECT * 查询 |## 阻断项详情### 测试覆盖率覆盖率52.0%低于阈值70%。缺失覆盖的类:- ReconciliationService (35%)- AlipayAdapter (20%)- DiffProcessor (40%)建议补充以下测试:1. ReconciliationService.compare() 的正常和异常流程测试2. AlipayAdapter.fetchBill() 的超时和重试测试3. DiffProcessor.process() 的边界值测试5. 研发执行Agent与编码工具的协作模型
5.1 工作流分工
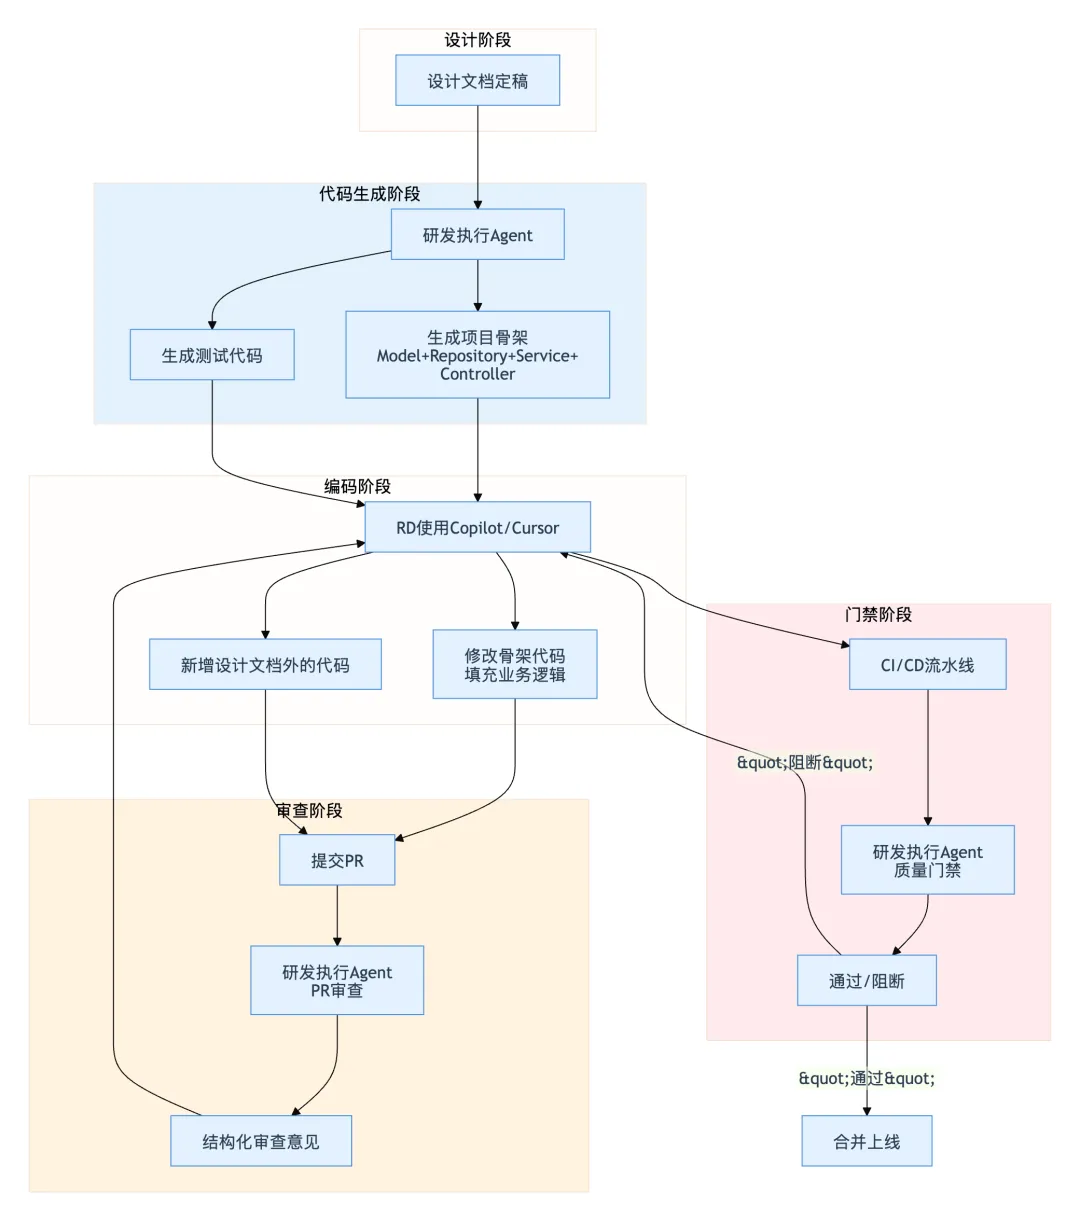
5.2 三层协作模型
关键原则:Agent生成骨架和审查,RD填充逻辑和做业务决策。两者不是替代关系,而是分工协作。
6. 效率提升与质量度量
6.1 效率对比
| 总计 | 1.8天 | 0.35天 | 5x |
6.2 质量指标
7. 本篇小结
核心观点回顾
研发执行Agent的核心差异是"理解设计文档"——Copilot/Cursor理解代码上下文,Agent理解设计文档,两者互补
代码生成从设计文档驱动——读取设计文档中的接口定义、数据模型、业务流程,生成Model/Repository/Service/Controller骨架+测试代码
PR审查是Agent作为第一个Reviewer——五个维度审查:设计一致性、代码规范、Bug检测、安全风险、性能问题,产出结构化审查意见
质量门禁嵌入CI/CD流水线——六个门禁:设计一致性(阻断)、测试覆盖率(阻断)、安全扫描(阻断)、日志埋点(非阻断)、异常处理(非阻断)、SQL性能(非阻断)
三层协作模型——Agent生成骨架+审查+门禁,RD+Copilot填充逻辑,各自发挥优势
代码生成不是替代RD编码——Agent生成的骨架需要RD修改完善,填充业务逻辑。Agent的价值是减少机械性翻译工作,让RD专注在业务逻辑实现上
记住:研发执行Agent不是要替代RD写代码,而是要成为RD的"第一个助手"——帮RD把设计文档翻译成代码骨架、帮RD做第一轮PR审查、帮RD在CI流水线里守质量底线。RD的价值不在写Model/Controller的getter/setter,而在设计业务逻辑、处理边界条件、做技术权衡。Agent把这些机械性工作接管了,RD才能真正专注于高价值工作。