 夜雨聆风
近期 Firecrawl 团队发布了一个开源超强的跨平台文档转换器 - anydoc。它能将 Word, PowerPoint, Excel, OpenDocument, RTF, EPUB, CSV, 和 PDF 等 14 种文档,快速地转换成干净的 Markdown 文档。
Anydoc 的特点
内置 Agent Skill,可快速集成到各种 Agent 平台。 处理速度快、跨平台,基于 Rust 构建,并提供了 Node.js 和 Python bindings。 支持非扫描的 PDF 文档,直接本地运行,无需使用 OCR 服务。 基于二进制数据识别文档格式,即使扩展名有误,也能实现正确转换。 支持多种不同格式文档转换,内置统一文档模型和 Markdown 序列化器,确保一致渲染效果。
目前 anydoc 支持以下文档类型:
Word: .doc, .docx, .docm PowerPoint: .ppt, .pps, .pot, .pptx, .pptm, .ppsx, .ppsm Excel: .xls, .xlsx, .xlsm, .xlsb OpenDocument: .odt, .ods, .odp Rich Text Format: .rtf EPUB: .epub CSV: .csv PDF: .pdf
Anydoc 性能
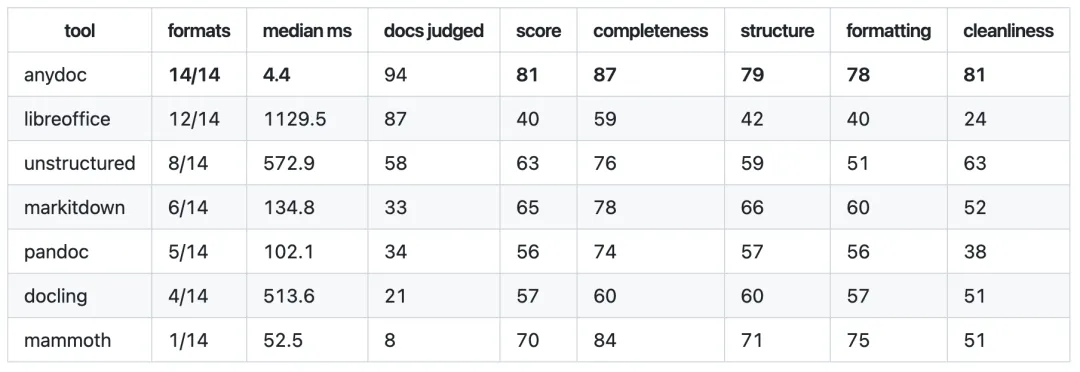
Anydoc 与 6 款主流转换器进行对比,测试范围覆盖 14 种格式的 100 份实际文档,评分范围 0 到 100 分,分数越高越好。
Anydoc 在线示例
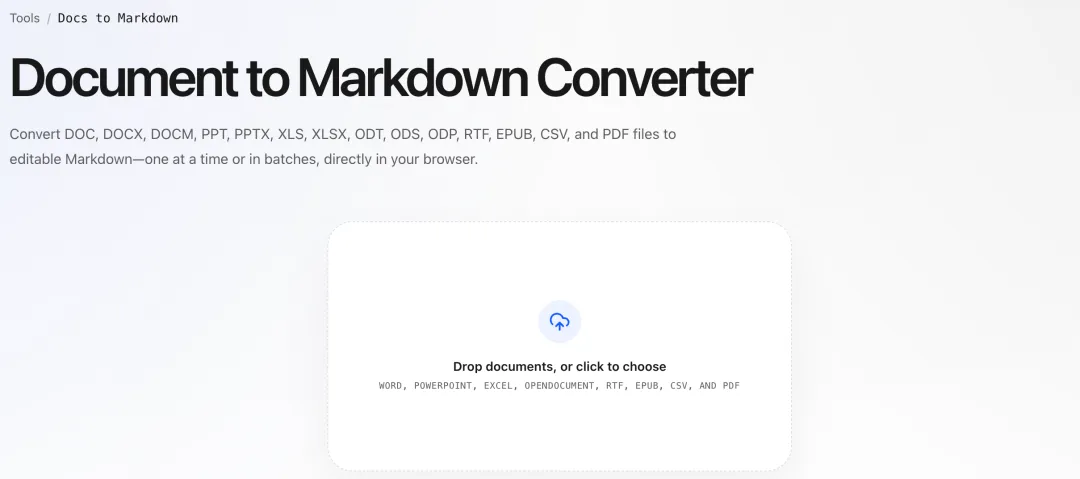
在浏览器中,打开 https://batchtool.com/tools/docs-to-markdown 地址,然后把待处理的文档拖入 "Drop documents" 区域,即可实现文档转换。
本地部署
CLI
npx @firecrawl/anydoc report.docx # Markdown to stdoutnpx @firecrawl/anydoc slides.pptx -o slides.md # or to a filenpx @firecrawl/anydoc - --format csv < data.csv # read stdinNode.js
安装 @firecrawl/anydoc 模块
npm install @firecrawl/anydoc# Orpnpm add @firecrawl/anydoc使用 @firecrawl/anydoc
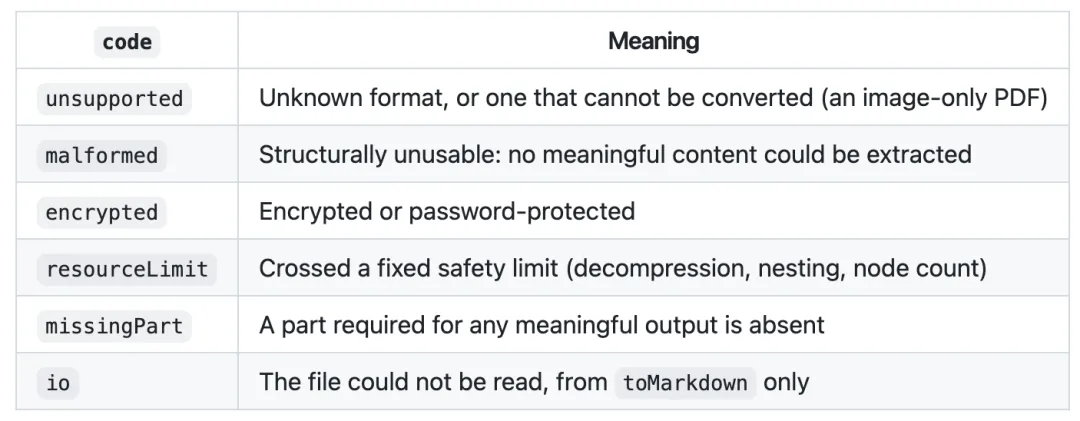
import { toDocument, toMarkdown, toMarkdownBytes } from'@firecrawl/anydoc';// From a file path:const markdown = await toMarkdown('report.docx');// From bytes, with the format detected from the content:const fromBytes = await toMarkdownBytes(bytes);// Or stop at the document model, which also carries embedded assets.// Unsupported for `pdf`constdocument = await toDocument(bytes);在实际文档场景中,要使用 try...catch 语句,捕获转换中的错误。比如,当你转换只包含纯图片的 PDF 文件时,会跑出异常,错误码为 "unsupported"。
如果你想要在浏览器中使用 anydoc,则需要使用 @firecrawl/anydoc-wasm 这个模块。
Agent SKill
如果你想要在 Claude Code、Codex、Cursor 或 OpenCode 中使用 anydoc,你需要先安装 anydoc 内置的 Agent skill:
npx skills add firecrawl/anydoc转换 PDF 文档
目前 Anydoc 不支持处理由纯图片构成的 PDF 文档,针对这种场景,我们可以集成 PaddlePaddle 开源的 PP-OCRv6。该模型支持 50 种语言,包含简体中文、繁体中文、英语、日语以及 46 种使用拉丁字母的语言。
接下来,我将介绍如何在 Node.js 和浏览器平台中,使用 ppu-paddle-ocr 模块,来运行 PP-OCRv6 模型。
安装 ppu-paddle-ocr 模块
pnpm add ppu-paddle-ocr onnxruntime-web # Browserpnpm add ppu-paddle-ocr onnxruntime-node # Node or Bun运行 PP-OCRv6 模型
import { readFileSync } from"node:fs";import { PaddleOcrService } from"ppu-paddle-ocr";const service = new PaddleOcrService({debugging: {debug: false,verbose: true, },});asyncfunctionmain() {await service.initialize();try {const image = readFileSync("./assets/pp-ocrv6-models.jpg");const imageBuffer = image.buffer.slice( image.byteOffset, image.byteOffset + image.byteLength, );const result = await service.recognize(imageBuffer);console.log(result.text); } finally {await service.destroy(); }}main().catch((error) => {console.error(error); process.exitCode = 1;});以上示例用于在 Node.js 或 Bun 中执行文字识别。如果你想要在浏览器环境中,运行文字识别。则需要使用 ppu-paddle-ocr/web 导出的 PaddleOcrService。
import { PaddleOcrService } from"ppu-paddle-ocr/web";const service = new PaddleOcrService();await service.initialize();const file = document.getElementById("upload").files[0];const img = new Image();img.src = URL.createObjectURL(file);awaitnewPromise((r) => (img.onload = r));const canvas = document.createElement("canvas");canvas.width = img.width;canvas.height = img.height;canvas.getContext("2d").drawImage(img, 0, 0);const result = await service.recognize(canvas);console.log(result.text);总结
有了 anydoc 这个库,我们可以在多个不同环境或平台中,方便地实现文档转换功能。如果你只需处理 PDF 文档,可以只使用 firecrawl 团队开发的 pdf-inspector 库。不过它也不支持处理由图片构成的 PDF 文档,仍需要自行集成 OCR 服务。我已经在实际的图片翻译项目中,集成了 PP-OCRv6 Medium 模型,精确度还是挺不错的。