ARTICLE · 1126869
人间灯市·生图源码
人间灯市·生图源码上图: 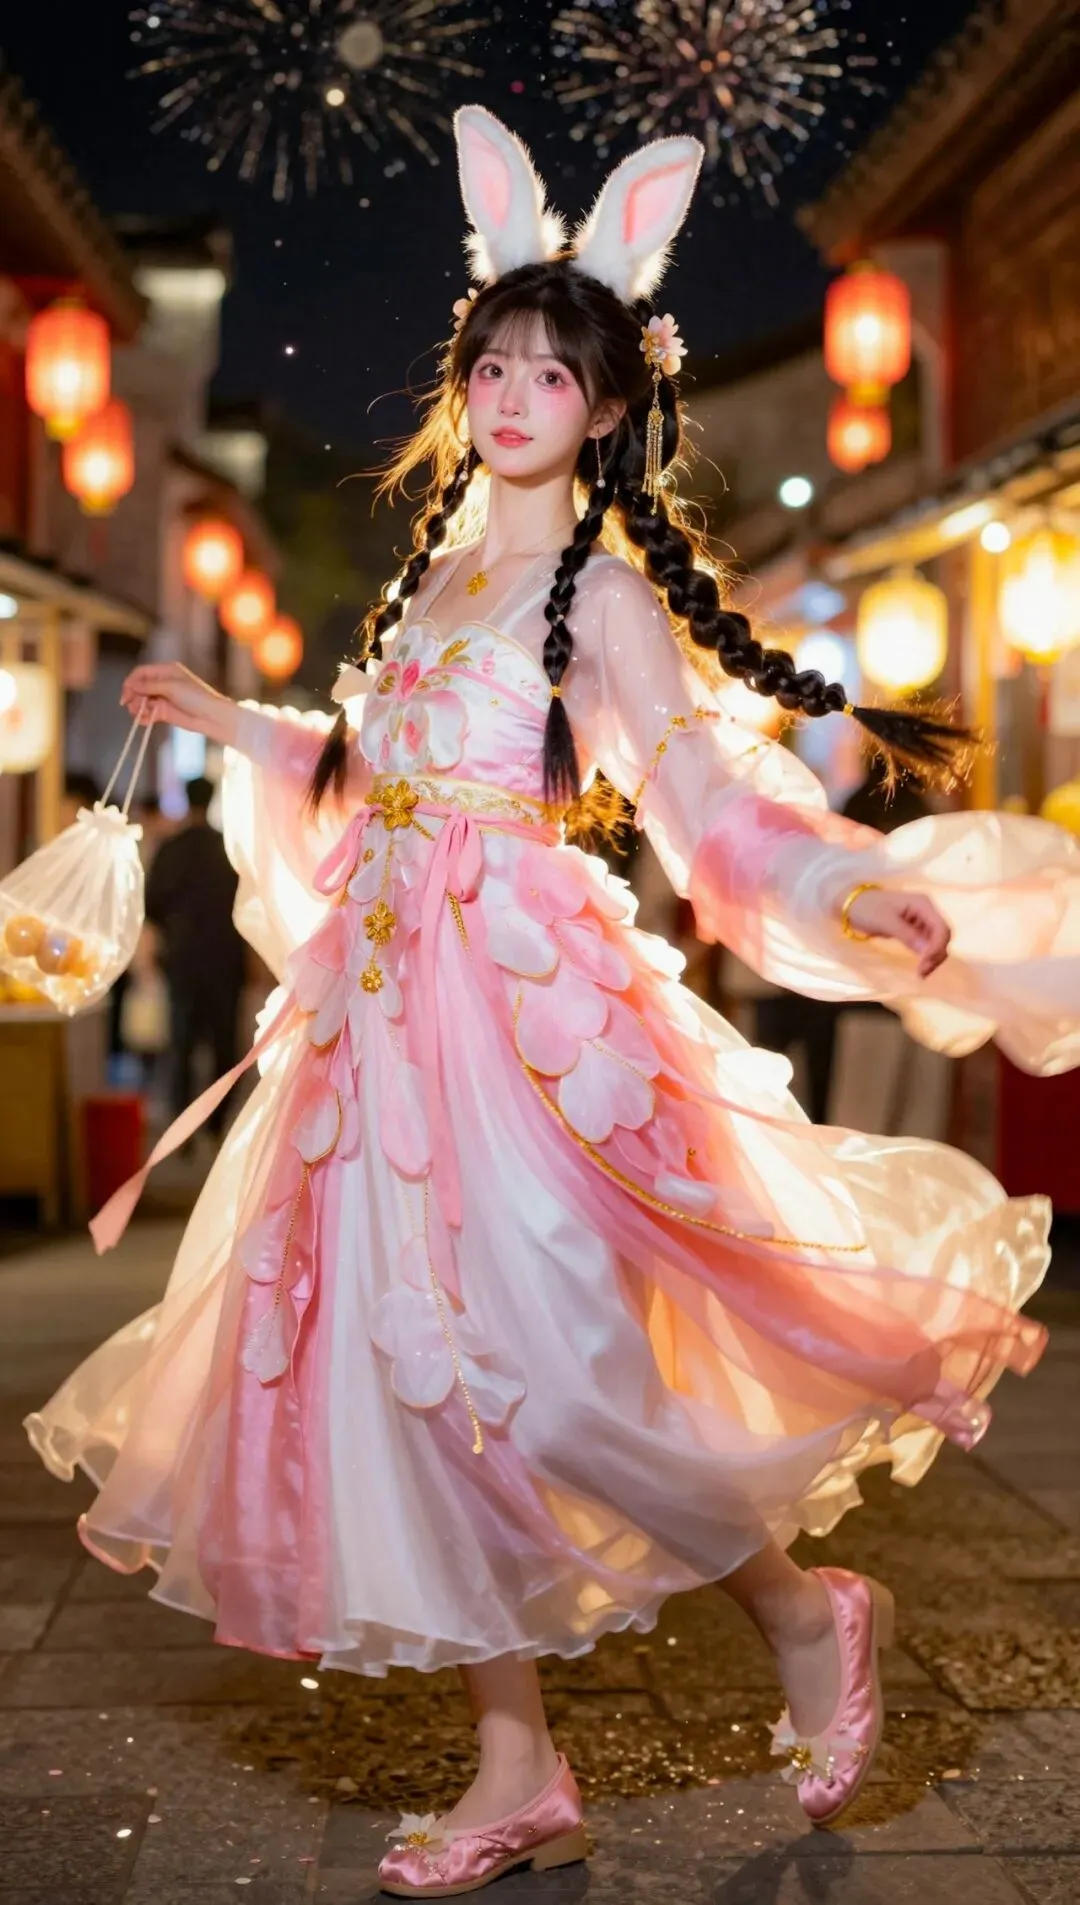
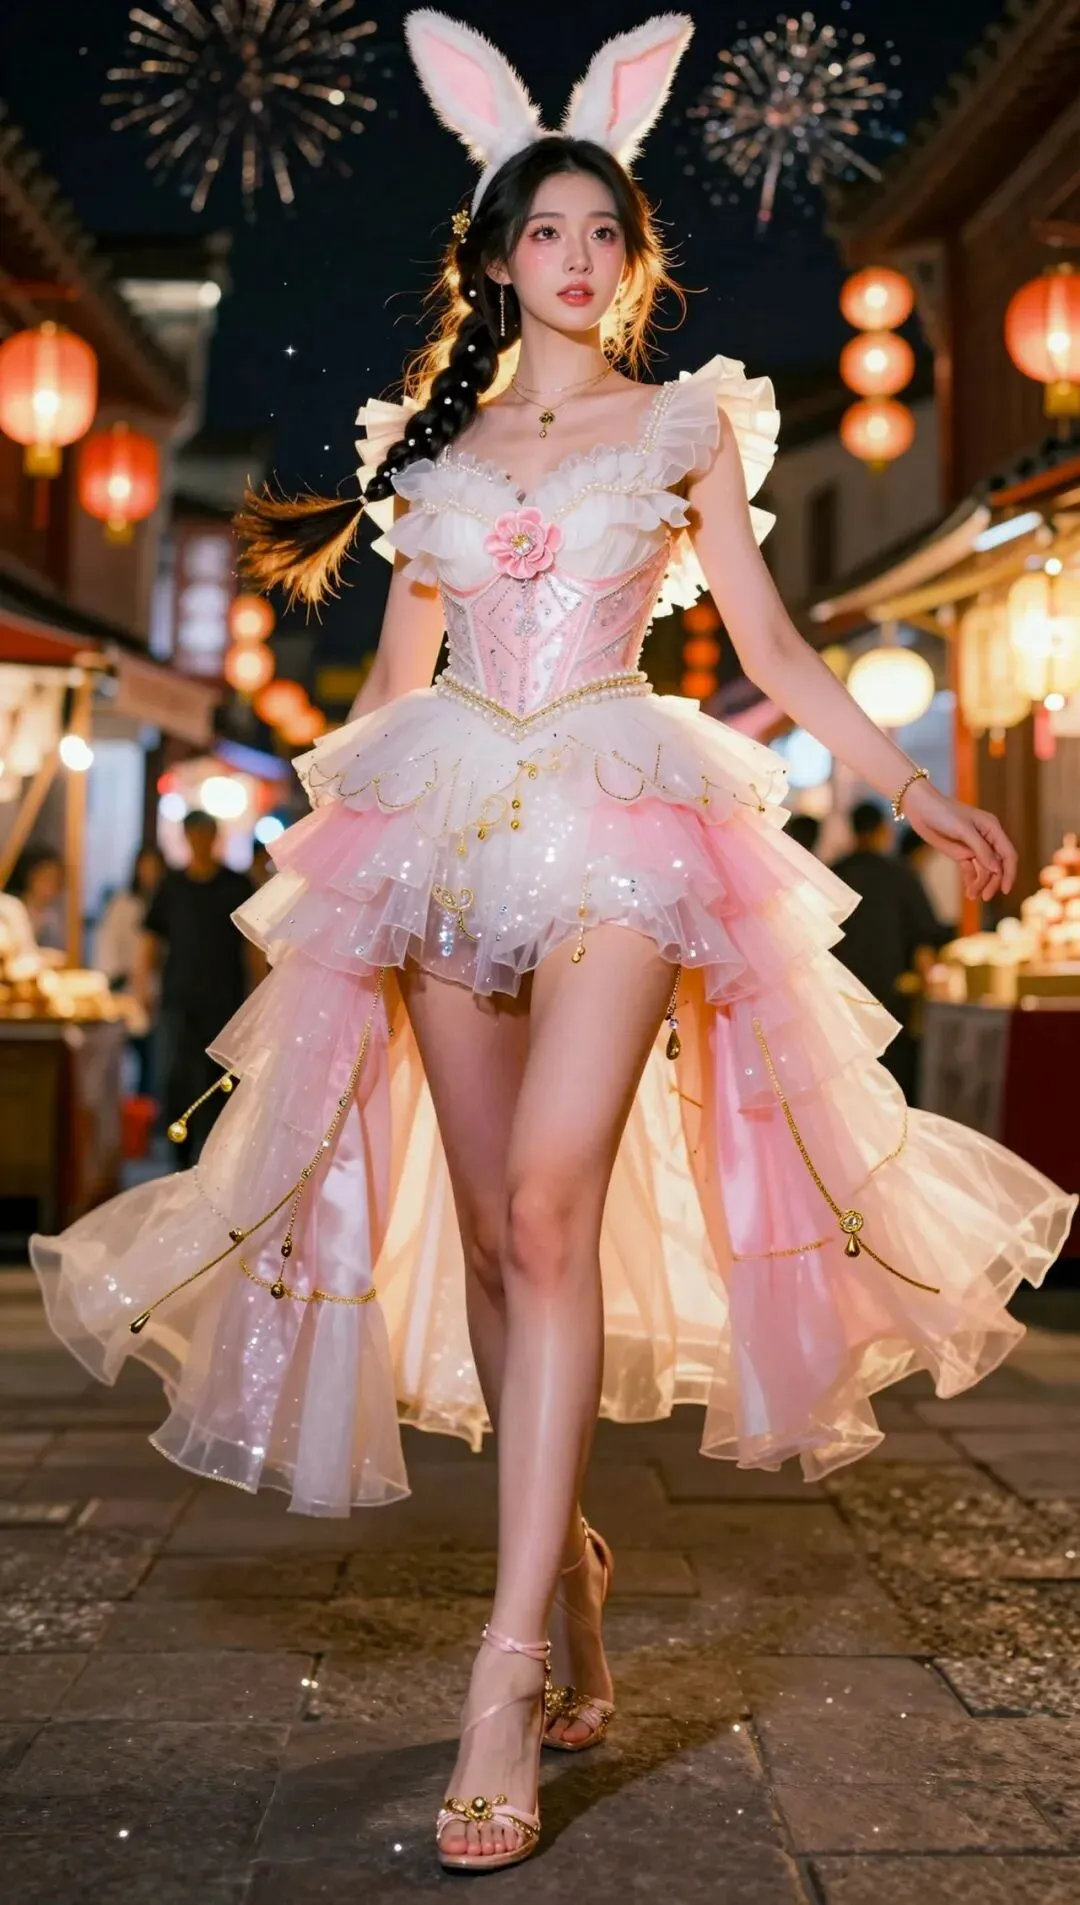
图太多了,上传不方便,去看贴图吧。 先上源码吧,源码直接用workbuddy自动生成,固定提示词定好背景和衣服,用动态节点切换20种人物动作,一气呵成,想要多少就可以,哇哈哈。 再上提示词:
#!/usr/bin/env python3# -*- coding: utf-8 -*-"""dengshi_batch.py —— 「人间灯市」系列图批量生成(ComfyUI API + Z-Image-Turbo)================================================================================一条命令把某一「篇」的所有变量提示词跑完,出图直接落到该篇目录里。--------------------------------------------------------------------------------它怎么知道要出什么图?--------------------------------------------------------------------------------不去猜:**直接读你手写的那几个 md 文件**。人间灯市 · 童话篇.md人间灯市 · 盛夏篇.md人间灯市 · 甜梦篇.md...每个 md 里有两块:「固定提示词」——整篇共用的镜头/人物/服装/光效,一条长 prompt「变量提示词」——20 条动作/表情,一条出一张图脚本把两块拼起来 = 一张图的完整 prompt。所以**加新篇不用改代码**,新建一个 `人间灯市 · XX篇.md` 照格式写好,`--list` 就能看到它。★ 推荐在固定提示词里放一个 `{动作}` 占位符,例如:面部是画面唯一实焦区域,{动作},层层裙摆在焦外晕染成……↑ 动作就插在这里不放也行:脚本会自动插在「面部是画面唯一实焦区域」后面;连这句都没有,就追加到末尾。--------------------------------------------------------------------------------用法--------------------------------------------------------------------------------# 看看现在有多少篇、每篇多少条(新增篇目后先跑这个)python dengshi_batch.py --list# 只拼提示词不出图,确认一下拼得对不对(强烈建议首次先跑)python dengshi_batch.py --chapter 童话 --dry-run# 正式出图:只跑童话篇 20 张python dengshi_batch.py --chapter 童话# 一次跑多篇(ComfyUI 只启一次,省启动时间)python dengshi_batch.py --chapter 童话 盛夏 甜梦python dengshi_batch.py --all# 先出 3 张试速度python dengshi_batch.py --chapter 童话 --limit 3# 只补某几条变量(第 5、9 条重出:先 --reset 清账,再 --only)python dengshi_batch.py --chapter 童话 --reset --only 5,9# 看进度(不启动 ComfyUI)python dengshi_batch.py --chapter 童话 --status# 中断了/显存爆了,原样重跑即可自动续跑(已出的图不重跑)python dengshi_batch.py --chapter 童话# 同一天想再跑一轮(换种子,动作不变)python dengshi_batch.py --chapter 童话 --run 20260916b# ComfyUI 已经手动开着python dengshi_batch.py --chapter 童话 --skip-start --keep-server--------------------------------------------------------------------------------输入 / 输出--------------------------------------------------------------------------------输入 ./人间灯市 · XX篇.md输出 ./人间灯市 · XX篇/{run}_{篇名}_{NN}.png ← 图,直接落在篇目录里./人间灯市 · XX篇/{run}_prompts.md ← 当天 prompt 清单(含 JSON 块)./人间灯市 · XX篇/{run}_index.csv ← 图 ↔ prompt 对照表./人间灯市 · XX篇/progress_{run}.txt ← 进度账本,用于断点续跑./.comfy_output/{run}/ ← ComfyUI 的临时输出(图会拷到篇目录)--------------------------------------------------------------------------------出图参数(与 web 工作流 zimage_web_workflow.json 逐项对齐)--------------------------------------------------------------------------------cfg 1.0 ★ 蒸馏模型官方值。设 >1.0 会让 ComfyUI 每步跑两次 UNet,直接慢一倍size 1088x1920(≈2.09MP)—— 与你现有灯市图的原始尺寸一致,再 2 倍放大得到 2176x3840,跟已出的图完全同规格(8GB 显存紧张时把 size 降到 768x1344,出图崩坏风险也更低)steps 8 / euler / simple / denoise 1.0 / AuraFlow shift 3.0依赖:仅 Python 标准库。"""import osimport reimport csvimport sysimport jsonimport timeimport shutilimport argparseimport datetimeimport subprocessimport urllib.requestimport urllib.errorimport urllib.parseimport zlibtry:sys.stdout.reconfigure(encoding='utf-8')except Exception:passHERE = os.path.dirname(os.path.abspath(__file__))# ============================ 路径 / 常量 ============================PREFIX = "人间灯市" # md 文件名前缀:「人间灯市 · XX篇.md」FIXED_KEY = "固定" # 固定提示词块的识别关键字VAR_KEY = "变量" # 变量提示词块的识别关键字SLOT_RE = re.compile(r"\{(?:动作|变量|action|pose)\}")FENCE_RE = re.compile(r"^\s*(?:~~~+|```+)")NUM_LINE_RE = re.compile(r"^(?:[-*+]\s+|\d+\s*[.、))]\s*)(\S.*)$")PROGRESS_TMPL = "progress_{run}.txt"INDEX_TMPL = "{run}_index.csv"PROMPTS_TMPL = "{run}_prompts.md"COMFY_OUT = ".comfy_output" # ComfyUI 临时输出根目录(在脚本同目录下)# 三个必须的模型文件MODELS = [("unet", "z-image-turbo-Q6_K.gguf", "Z-Image-Turbo 扩散模型 (GGUF Q6_K)"),("text_encoders", "Qwen3-4B-Q4_K_M.gguf", "Qwen3-4B 文本编码器 (GGUF Q4_K_M)"),("vae", "ae.safetensors", "VAE 解码器"),]NEEDED_NODES = ["KSampler", "UnetLoaderGGUF", "VAELoader", "CLIPLoaderGGUF", "CLIPTextEncode","ModelSamplingAuraFlow", "EmptySD3LatentImage", "ConditioningZeroOut", "VAEDecode","PreviewImage",]COMFYUI_CANDIDATES = [r"D:\python\libib\LiblibAI-workspace\LiblibAI-workspace\comfyui-deploy-win\ComfyUI",r"D:\LiblibAI-workspace\comfyui-deploy-win\ComfyUI",r"D:\comfyui-deploy-win\ComfyUI",r"C:\comfyui-deploy-win\ComfyUI",]SAVE_NODE_ID = "9"DEFAULT_SEED_BASE = 20240916# ============================ md 解析 ============================def split_blocks(text):"""把 md 切成 [(块前的标签行, 块内容), ...]。标签行 = 围栏开始前最近的一行非空文本(用来判断这块是「固定」还是「变量」)。支持 ~~~~ 和 ``` 两种围栏。"""blocks, buf, label, in_block, fence = [], [], "", False, ""for raw in text.splitlines():if not in_block and FENCE_RE.match(raw):in_block, fence, buf = True, raw.strip()[:3], []continueif in_block:if raw.strip().startswith(fence):blocks.append((label, "\n".join(buf)))in_block, buf = False, []else:buf.append(raw)continueif raw.strip():label = raw.strip()if in_block and buf: # 文件末尾没闭合,也认blocks.append((label, "\n".join(buf)))return blocksdef parse_vars(text):"""从变量块里抽出条目(去掉 1. / - 前缀和行尾注释)。"""out = []for raw in text.splitlines():line = raw.strip()if not line or line.startswith("![[") or line.startswith("#"):continuem = NUM_LINE_RE.match(line)if not m:continuev = m.group(1).strip().strip("*`").strip(",,。;;::")v = re.split(r"\s+#\s*", v)[0].strip()if v and v not in out:out.append(v)return outdef parse_chapter(path):"""解析一个篇章 md → {title, fixed, vars, slot}。解析不出固定提示词就报错。"""with open(path, "r", encoding="utf-8", errors="replace") as f:text = f.read()title = re.sub(r"^%s\s*[·・\-]\s*" % re.escape(PREFIX), "",os.path.splitext(os.path.basename(path))[0]).strip()blocks = split_blocks(text)fixed = Nonefor label, body in blocks:if FIXED_KEY in label and body.strip():fixed = body.strip()breakif fixed is None: # 没有标签线索:拿最长的那块当固定提示词cands = [b.strip() for _, b in blocks if len(b.strip()) > 60]if cands:fixed = max(cands, key=len)if not fixed:raise ValueError("没找到「固定提示词」块(需用 ~~~ 或 ``` 围起来)")variants = Nonefor label, body in blocks:if VAR_KEY in label and body.strip():variants = parse_vars(body)if variants:breakif not variants: # 兜底:找编号行最多的那块best = []for _, body in blocks:got = parse_vars(body)if len(got) > len(best):best = gotvariants = bestif not variants:raise ValueError("没找到「变量提示词」条目(每行一条,如 `1. 动作描述`)")slot = bool(SLOT_RE.search(fixed))return {"path": path,"title": title,"dir": os.path.join(HERE, os.path.splitext(os.path.basename(path))[0]),"fixed": re.sub(r"\s+", "", fixed),"vars": variants,"slot": slot}def find_chapters():"""扫出脚本同目录下所有「人间灯市 · XX篇.md」(篇名必须以「篇」结尾,这样「人间灯市 · 篇目提案.md」这类说明文档不会被误当成篇目)。"""out = []for fn in sorted(os.listdir(HERE)):if not fn.endswith(".md") or not fn.startswith(PREFIX):continueif not re.match(r"^%s\s*[·・\-]\s*.+篇\.md$" % re.escape(PREFIX), fn):continuepath = os.path.join(HERE, fn)try:out.append(parse_chapter(path))except Exception as e:print(f"⚠ 跳过 {fn}:{e}")return outdef match_chapters(chapters, wanted):"""按用户输入匹配篇目:支持「童话」「童话篇」「人间灯市 · 童话篇」等写法。"""picked, miss = [], []for w in wanted:key = re.sub(r"\.md$", "", w.strip())key = re.sub(r"^%s\s*[·・\-]\s*" % re.escape(PREFIX), "", key)key = re.sub(r"[篇\s]", "", key)hit = [c for c in chaptersif key and (key in re.sub(r"[篇\s]", "", c["title"])or re.sub(r"[篇\s]", "", c["title"]) in key)]if not hit:miss.append(w)for h in hit:if h not in picked:picked.append(h)return picked, miss# ============================ prompt 拼接 ============================def build_prompt(fixed, action):"""固定提示词 + 变量 → 完整 prompt。有 {动作} 占位就替换;没有就插在「面部是画面唯一实焦区域」后面(这句是每篇的构图锚点,动作紧跟其后权重最合适);再没有就追加到末尾。"""act = action.strip().rstrip("。")if SLOT_RE.search(fixed):return SLOT_RE.sub(act, fixed, count=1)key = "面部是画面唯一实焦区域,"if key in fixed:return fixed.replace(key, key + act + ",", 1)return fixed.rstrip(",,") + "," + act# ============================ ComfyUI ============================def find_comfyui(explicit):cands = []if explicit:cands.append(explicit)if os.environ.get("COMFYUI_PATH"):cands.append(os.environ["COMFYUI_PATH"])cands += COMFYUI_CANDIDATESfor c in cands:if c and os.path.isfile(os.path.join(c, "main.py")):return os.path.abspath(c)raise SystemExit("✗ 找不到 ComfyUI(需含 main.py)。请用 --comfyui 指定。")def find_embedded_python(comfyui_dir):parent = os.path.dirname(comfyui_dir)for c in (os.path.join(parent, "python_embeded", "python.exe"),os.path.join(parent, "python_embeded", "python"),os.path.join(comfyui_dir, "python_embeded", "python.exe")):if os.path.isfile(c):return cfor name in ("python", "python3"):exe = shutil.which(name)if exe:return exeraise SystemExit("✗ 找不到 Python 解释器。")def resolve_models_base(comfyui_dir, explicit):if explicit:return os.path.abspath(explicit)args_json = os.path.join(comfyui_dir, "comfyui_args.json")if os.path.isfile(args_json):try:with open(args_json, "r", encoding="utf-8") as f:cfg = json.load(f)for item in cfg.get("args", []):if item.get("name") == "model-dir" and item.get("value"):return os.path.abspath(item["value"])except Exception:passsibling = os.path.abspath(os.path.join(os.path.dirname(comfyui_dir), "..", "Models"))return sibling if os.path.isdir(sibling) else os.path.join(comfyui_dir, "models")def start_server(comfyui_dir, py, port, models_base, vram, extra_args, log_path, output_dir):deploy_root = os.path.dirname(comfyui_dir)yaml_path = os.path.join(deploy_root, "comfyui_extra_paths.yaml")if not os.path.isfile(yaml_path):mb = models_base.replace("\\", "/").rstrip("/") + "/"with open(yaml_path, "w", encoding="utf-8") as f:f.write("comfyui:\n base_path: %s\n checkpoints: checkpoints/\n clip: clip/\n"" text_encoders: text_encoders/\n unet: unet/\n diffusion_models: diffusion_models/\n"" vae: vae/\n loras: loras/\n upscale_models: upscale_models/\n"" clip_vision: clip_vision/\n embeddings: embeddings/\n"" controlnet: controlnet/\n diffusers: diffusers/\n ipadapter: ipadapter/\n" % mb)cmd = [py, "-s", "ComfyUI/main.py", "--windows-standalone-build","--listen", "127.0.0.1", "--port", str(port), "--disable-auto-launch","--extra-model-paths-config", yaml_path, "--output-directory", output_dir]if vram and vram != "none":cmd.append("--" + vram)cmd += extra_argslog = open(log_path, "w", encoding="utf-8", errors="ignore")return subprocess.Popen(cmd, cwd=deploy_root, stdout=log, stderr=subprocess.STDOUT)def server_ready(base, timeout=300):deadline = time.time() + timeoutwhile time.time() < deadline:try:urllib.request.urlopen(base + "/", timeout=5)return Trueexcept Exception:time.sleep(2)return Falsedef is_comfyui(base, timeout=5):"""确认 base 上跑的确实是 ComfyUI:/system_stats 是它独有接口。"""try:with urllib.request.urlopen(base + "/system_stats", timeout=timeout) as r:d = json.loads(r.read().decode("utf-8"))return isinstance(d, dict) and "system" in d and "devices" in dexcept Exception:return Falsedef pick_port(start, span=10):"""从 start 起找可用端口:优先「已在跑 ComfyUI 的」,其次「空闲的」。"""for p in range(start, start + span):b = f"http://127.0.0.1:{p}"if server_ready(b, timeout=2):if is_comfyui(b):print(f" → 发现 ComfyUI 跑在 {p} 端口,改用它")return b, p, Truecontinueprint(f" → 改用空闲端口 {p}")return b, p, Falsereturn None, start, Falsedef wait_ready(base, timeout=300, proc=None):"""等 ComfyUI 真正可用:HTTP 通 + 节点注册完成(/object_info 里有 KSampler)。"""deadline = time.time() + timeoutt0 = time.time()t_print = 0while time.time() < deadline:if proc is not None and proc.poll() is not None:print(f" ! ComfyUI 进程已退出(返回码 {proc.returncode})")return Falsetry:urllib.request.urlopen(base + "/", timeout=5)except Exception:time.sleep(2)continuetry:info = api_post(base, "/object_info")if isinstance(info, dict) and "KSampler" in info:return Trueexcept Exception:passel = int(time.time() - t0)if el - t_print >= 15:print(f" ... 服务已响应,等待节点注册完成(已等 {el}s)")t_print = eltime.sleep(2)return Falsedef tail_log(path, n=25):try:with open(path, "r", encoding="utf-8", errors="ignore") as f:lines = f.readlines()return "".join(lines[-n:]).strip() or "(日志为空)"except Exception:return "(读不到日志: %s)" % pathdef kill_port(port):"""杀掉占用指定端口的进程(仅在确认是 ComfyUI 之后才调用)。"""try:out = subprocess.check_output(["netstat", "-ano"],stderr=subprocess.DEVNULL).decode("utf-8", "ignore")except Exception:return Falsefor line in out.splitlines():if (":%d " % port) in line and "LISTENING" in line:pid = line.split()[-1].strip()if pid.isdigit():try:subprocess.run(["taskkill", "/F", "/PID", pid], check=False,stdout=subprocess.DEVNULL, stderr=subprocess.DEVNULL)return Trueexcept Exception:return Falsereturn Falsedef api_post(base, path, data=None):if data is not None:req = urllib.request.Request(base + path,data=json.dumps(data).encode("utf-8"),headers={"Content-Type": "application/json"})else:req = urllib.request.Request(base + path)try:with urllib.request.urlopen(req, timeout=180) as r:return json.loads(r.read().decode("utf-8"))except urllib.error.HTTPError as e:body = ""try:body = e.read().decode("utf-8", "ignore")except Exception:passraise RuntimeError("HTTP %s @ %s : %s" % (e.code, path, body[:500]))def api_get_bytes(base, path, params):url = base + path + "?" + urllib.parse.urlencode(params)with urllib.request.urlopen(url, timeout=300) as r:return r.read()def build_workflow(prompt, seed, width, height, steps, prefix, cfg=1.0, unet_name=None,upscale=1.0, upscale_method="lanczos"):"""Z-Image-Turbo (GGUF) 工作流,API 格式。upscale > 1 时在 VAEDecode(8) 后面接一个 ImageScaleBy(40),存图节点(9) 改接放大结果 —— 最终尺寸 = width*upscale x height*upscale。"""wf = {"3": {"class_type": "KSampler", "inputs": {"seed": seed, "steps": steps, "cfg": cfg,"sampler_name": "euler", "scheduler": "simple", "denoise": 1.0,"model": ["11", 0], "positive": ["27", 0],"negative": ["33", 0], "latent_image": ["13", 0]}},"8": {"class_type": "VAEDecode", "inputs": {"samples": ["3", 0], "vae": ["29", 0]}},"9": {"class_type": "PreviewImage", "inputs": {"images": ["8", 0], "filename_prefix": prefix}},"11": {"class_type": "ModelSamplingAuraFlow", "inputs": {"model": ["28", 0], "shift": 3.0}},"13": {"class_type": "EmptySD3LatentImage", "inputs": {"width": width, "height": height, "batch_size": 1}},"27": {"class_type": "CLIPTextEncode", "inputs": {"text": prompt, "clip": ["30", 0]}},"28": {"class_type": "UnetLoaderGGUF", "inputs": {"unet_name": unet_name or MODELS[0][1]}},"29": {"class_type": "VAELoader", "inputs": {"vae_name": MODELS[2][1]}},"30": {"class_type": "CLIPLoaderGGUF", "inputs": {"clip_name": MODELS[1][1], "type": "qwen3_4b"}},"33": {"class_type": "ConditioningZeroOut", "inputs": {"conditioning": ["27", 0]}},}if upscale and upscale > 1.0:wf["40"] = {"class_type": "ImageScaleBy", "inputs": {"upscale_method": upscale_method, "scale_by": upscale, "image": ["8", 0]}}wf["9"]["inputs"]["images"] = ["40", 0]return wfdef submit_prompt(base, client_id, workflow):r = api_post(base, "/prompt", {"prompt": workflow, "client_id": client_id})return r["prompt_id"]def wait_result(base, prompt_id, timeout=900, poll=1.0):deadline = time.time() + timeoutdead = 0while time.time() < deadline:try:hist = api_post(base, f"/history/{prompt_id}")dead = 0except Exception:hist = {}dead += 1if dead >= 5:raise RuntimeError(f"ComfyUI 服务已断开(连续 {dead} 次连不上 {base})\n"" 多半是显存爆了导致进程崩溃 —— 看 dengshi_comfyui.log 末尾,\n"" 出现 'loaded partially' 或 'Stopped server' 就是显存不够。\n"" 处理:关掉占显存的程序 → 重跑(会自动续跑)→ 或加 --size 768x1344")if prompt_id in hist:entry = hist[prompt_id]if entry.get("outputs"):return entry["outputs"]if entry.get("status", {}).get("status_str") == "error":raise RuntimeError("生成失败: %s" % entry["status"].get("messages", []))time.sleep(poll)raise TimeoutError("生成超时(%ss)" % timeout)def models_loaded_in_server(base, unet_name):try:info = api_post(base, "/object_info/UnetLoaderGGUF")except Exception:return Truen = list(info.keys())[0]try:return unet_name in info[n]["input"]["required"]["unet_name"][0]except Exception:return True# ============================ 小工具 ============================def safe_name(s):return re.sub(r'[\\/:*?"<>|]+', "_", s).strip()def stable_hash(s):"""跨进程稳定的字符串哈希(Python 的 hash() 有随机化,不能用)。"""return zlib.crc32(s.encode("utf-8"))def load_progress(path):done = set()if os.path.isfile(path):with open(path, "r", encoding="utf-8") as f:for line in f:line = line.strip()if line.isdigit():done.add(int(line))return donedef append_progress(path, idx):with open(path, "a", encoding="utf-8") as f:f.write(f"{idx}\n")f.flush()os.fsync(f.fileno())def write_prompts_md(path, run, tasks):with open(path, "w", encoding="utf-8") as f:f.write(f"# 人间灯市 · {tasks[0]['chapter']} · prompts({run})\n\n")f.write(f"- 共 {len(tasks)} 条\n")f.write(f"- 出图尺寸 {tasks[0]['size']}"+ (f" → 放大 {tasks[0]['up']:g} 倍" if tasks[0]['up'] > 1 else "")+ "\n")f.write(f"- 种子基数 {tasks[0]['seed_base']}\n\n")f.write("| # | 文件名 | 动作 |\n|---|---|---|\n")for t in tasks:f.write(f"| {t['idx']} | {t['fname']} | {t['action']} |\n")f.write("\n<!-- PROMPTS_JSON_START -->\n")f.write(json.dumps([{"idx": t["idx"], "fname": t["fname"],"action": t["action"], "seed": t["seed"],"prompt": t["prompt"]} for t in tasks],ensure_ascii=False, indent=1))f.write("\n<!-- PROMPTS_JSON_END -->\n")def write_index_csv(path, tasks):with open(path, "w", encoding="utf-8-sig", newline="") as f:wr = csv.writer(f)wr.writerow(["filename", "idx", "chapter", "action", "seed", "prompt"])for t in tasks:if os.path.isfile(t["fpath"]) and os.path.getsize(t["fpath"]) > 0:wr.writerow([t["fname"], t["idx"], t["chapter"],t["action"], t["seed"], t["prompt"]])# ============================ main ============================def main():ap = argparse.ArgumentParser(description="人间灯市 · 系列图批量生成(Z-Image-Turbo / ComfyUI API)",formatter_class=argparse.RawDescriptionHelpFormatter)ap.add_argument("--chapter", "-c", nargs="*", default=[],help="要跑的篇:--chapter 童话 / --chapter 童话 盛夏 甜梦(模糊匹配)")ap.add_argument("--all", action="store_true", help="跑全部篇目")ap.add_argument("--list", action="store_true", help="只列出篇目和条目数就退出")ap.add_argument("--run", help="批次标识,默认今天日期 YYYYMMDD(同一天再跑一轮换个名字即可)")ap.add_argument("--only", help="只跑指定变量序号,如 5,9,12")ap.add_argument("--limit", type=int, default=0, help="每篇最多出 N 张(0=全部)")ap.add_argument("--reset", action="store_true", help="清空该批次进度账本(重跑)")ap.add_argument("--dry-run", action="store_true", help="只拼提示词并写 md,不出图")ap.add_argument("--status", action="store_true", help="只看进度,不出图")ap.add_argument("--size", default="1088x1920",help="初始出图尺寸 WxH,默认 1088x1920(与现有灯市图原图一致)。""显存紧张就降到 768x1344")ap.add_argument("--upscale", type=float, default=2.0,help="放大倍数(ImageScaleBy 节点,默认 2.0 → 2176x3840;1 = 不放大)")ap.add_argument("--upscale-method", default="lanczos",choices=["nearest-exact", "bilinear", "area", "bicubic", "lanczos"],help="放大算法(默认 lanczos,画质最好;卡的话换 bicubic)")ap.add_argument("--steps", type=int, default=8, help="采样步数")ap.add_argument("--cfg", type=float, default=1.0, help="CFG,蒸馏模型用 1.0(>1.0 会慢一倍)")ap.add_argument("--seed", type=int, default=None,help="种子基数。不给则按批次名生成稳定种子(同批次重跑种子一致)")ap.add_argument("--timeout", type=int, default=300,help="单张超时(秒),默认 300。正常一张 60~90 秒(1088x1920)")ap.add_argument("--max-fails", type=int, default=3,help="连续失败 N 张就中止(默认 3,0 = 不中止)")ap.add_argument("--comfyui", help="ComfyUI 目录")ap.add_argument("--models-dir", help="模型根目录")ap.add_argument("--unet", help="unet 文件名")ap.add_argument("--port", type=int, default=8188)ap.add_argument("--skip-start", action="store_true", help="不启动 ComfyUI(假定已运行)")ap.add_argument("--keep-server", action="store_true", help="跑完不关闭 ComfyUI")ap.add_argument("--skip-models", action="store_true", help="跳过模型检查")ap.add_argument("--check", action="store_true", help="只检查节点是否齐全")ap.add_argument("--vram", default="none",choices=["none", "gpu-only", "highvram", "normalvram","lowvram", "novram", "cpu"],help="显存模式,默认 none(与 web 启动器一致),OOM 时用 lowvram")ap.add_argument("--extra-args", nargs="*", default=[])args = ap.parse_args()run = args.run or datetime.date.today().strftime("%Y%m%d")try:w, h = (int(x) for x in args.size.lower().split("x"))except Exception:raise SystemExit("✗ --size 格式应为 WxH,例如 1088x1920")only = set()if args.only:only = {int(m) for m in re.findall(r"\d+", args.only)}if not only:raise SystemExit("✗ --only 格式应为序号列表,如 5,9,12")# ---------- 1) 载入篇目 ----------chapters = find_chapters()if not chapters:raise SystemExit(f"✗ 同目录下没找到任何「{PREFIX} · XX篇.md」")if args.list:print(f"共 {len(chapters)} 篇:\n")for c in chapters:flag = "有 {动作} 占位" if c["slot"] else "无占位(自动插入)"n_done = len([1 for i in range(1, len(c["vars"]) + 1)if os.path.isfile(os.path.join(c["dir"], f"{run}_{safe_name(c['title'])}_{i:02d}.png"))])print(f" · {c['title']:<6}{len(c['vars']):>3} 条 [{flag}]"f" 已完成 {n_done}/{len(c['vars'])}(批次 {run})")print(f"\n批次标识:{run}(--run 可改)")returnif args.all:picked = chapterselif args.chapter:picked, miss = match_chapters(chapters, args.chapter)if miss:print(f"⚠ 没匹配到:{'、'.join(miss)}(可用 --list 看篇目列表)")if not picked:raise SystemExit("✗ 没有匹配到任何篇目")else:raise SystemExit("✗ 请指定要跑的篇:--chapter 童话,或 --all(--list 看全部)")# ---------- 2) 编任务 ----------up = args.upscale if args.upscale and args.upscale > 1.0 else 1.0ow, oh = int(w * up), int(h * up)seed_base = args.seed if args.seed is not None else stable_hash(run) % 100000plans = []print("=" * 60)for c in picked:os.makedirs(c["dir"], exist_ok=True)tasks = []for i, action in enumerate(c["vars"], 1):if only and i not in only:continuefname = f"{run}_{safe_name(c['title'])}_{i:02d}.png"fpath = os.path.join(c["dir"], fname)seed = (seed_base + stable_hash(f"{run}|{c['title']}|{i}")) % (2 ** 31)tasks.append({"idx": i, "chapter": c["title"], "action": action,"prompt": build_prompt(c["fixed"], action),"fname": fname, "fpath": fpath, "seed": seed,"size": f"{w}x{h}", "up": up, "seed_base": seed_base,})plan = {"chapter": c, "tasks": tasks}plans.append(plan)print(f"篇目 {c['title']}:{len(c['vars'])} 条变量"+ (f"(--only 取其中 {len(tasks)} 条)" if only else "")+ f" 输出 → {c['dir']}")if args.limit and args.limit > 0: # 只出前 N 张(每篇各自取前 N 张)for plan in plans:plan["tasks"] = plan["tasks"][:args.limit]print(f"(--limit {args.limit}:每篇只处理前 {args.limit} 条)")print(f"批次 {run}|{w}x{h}({w*h/1e6:.2f}MP)"+ (f" → 放大 {up:g} 倍 → {ow}x{oh}({ow*oh/1e6:.2f}MP)" if up > 1 else "(不放大)")+ f"|步数 {args.steps} CFG {args.cfg}")print("=" * 60)# ---------- 3) 写 prompts md + 算待跑 ----------total_todo = 0for plan in plans:c, tasks = plan["chapter"], plan["tasks"]md_path = os.path.join(c["dir"], PROMPTS_TMPL.format(run=run))write_prompts_md(md_path, run, tasks)pg_path = os.path.join(c["dir"], PROGRESS_TMPL.format(run=run))if args.reset and os.path.isfile(pg_path):os.remove(pg_path)print(f"已清空 {c['title']} 的进度账本({run})")done = load_progress(pg_path)plan["progress"] = pg_pathplan["done"] = doneplan["todo"] = [t for t in tasksif t["idx"] not in doneor not (os.path.isfile(t["fpath"]) and os.path.getsize(t["fpath"]) > 0)]total_todo += len(plan["todo"])print(f" {c['title']}:已完成 {len(tasks) - len(plan['todo'])}/{len(tasks)}"f" prompts → {os.path.basename(md_path)}")if args.status or args.dry_run:print()for plan in plans:c = plan["chapter"]nxt = plan["todo"][0]["idx"] if plan["todo"] else Noneprint(f" {c['title']}:{len(plan['tasks']) - len(plan['todo'])}/{len(plan['tasks'])}"+ (f",下一张 #{nxt}" if nxt else ",全部完成"))if args.dry_run and plan["tasks"]:t = plan["tasks"][0]print(f"\n【{c['title']} 第 1 条 prompt】\n{t['prompt']}\n")print(f"合计待跑 {total_todo} 张。")returnif total_todo == 0:print("\n全部出图已完成,无需重跑。(要重跑加 --reset)")for plan in plans:write_index_csv(os.path.join(plan["chapter"]["dir"], INDEX_TMPL.format(run=run)), plan["tasks"])return# ---------- 4) 启动 ComfyUI ----------comfyui = find_comfyui(args.comfyui)py = find_embedded_python(comfyui)models_base = resolve_models_base(comfyui, args.models_dir)unet_name = args.unet or MODELS[0][1]base = f"http://127.0.0.1:{args.port}"comfy_out = os.path.join(HERE, COMFY_OUT, run)os.makedirs(comfy_out, exist_ok=True)print(f"\nComfyUI : {comfyui}")print(f"模型目录: {models_base}")print(f"UNET : {unet_name}")if not args.skip_models:ok = Truefor sub, fname, desc in MODELS:actual = unet_name if sub == "unet" else fnamedest = os.path.join(models_base, sub, actual)if os.path.exists(dest) and os.path.getsize(dest) > 0:print(f" ✓ {actual} ({os.path.getsize(dest)//1024//1024} MB)")else:ok = Falseprint(f" ✗ 缺少: {dest}")if not ok:raise SystemExit("\n✗ 模型文件不齐。")log_path = os.path.join(HERE, "dengshi_comfyui.log")proc = Noneif args.skip_start:if not server_ready(base, timeout=15):raise SystemExit(f"✗ --skip-start 但 {base} 无响应")print(" ✓ 复用已运行的 ComfyUI" if is_comfyui(base)else f" ⚠ {base} 有响应,但 /system_stats 不像 ComfyUI,继续可能报错")else:up_now = server_ready(base, timeout=10)if up_now and not is_comfyui(base):print(f" 端口 {args.port} 有响应但不是 ComfyUI(可能别的程序占用)")base, args.port, up_now = pick_port(args.port)if base is None:raise SystemExit(f"✗ {args.port}~{args.port+9} 都被占用且没有 ComfyUI")if up_now and models_loaded_in_server(base, unet_name):print(" ✓ 复用已运行的 ComfyUI(模型已加载)")else:if up_now:print(" ComfyUI 在跑但没扫描到 GGUF 模型 —— 自动重启刷新 ...")kill_port(args.port)time.sleep(3)print(f" 启动 ComfyUI(端口 {args.port})...")proc = start_server(comfyui, py, args.port, models_base, args.vram,list(args.extra_args), log_path, comfy_out)if not wait_ready(base, timeout=300, proc=proc):print(f"✗ 启动失败。日志尾部:\n{'-'*46}\n{tail_log(log_path)}\n{'-'*46}")if proc:proc.terminate()raise SystemExit(1)print(" ✓ 服务就绪")if args.check:info = api_post(base, "/object_info")missing = [n for n in NEEDED_NODES if n not in info]print("✗ 缺少节点:" + str(missing) if missing else "✓ 节点齐全")if proc and not args.keep_server:proc.terminate()returnif args.cfg > 1.0:print(f" ⚠ CFG={args.cfg} > 1.0:每步要跑两次 UNet,耗时约翻倍")# 显存预检:Z-Image 模型本身要 5.6GB,装不下会走内存(单张从 1 分钟变十几分钟)try:st = api_post(base, "/system_stats")dev = (st.get("devices") or [{}])[0]free = dev.get("vram_free", 0)if free:if free < 6.2e9:print(f" ⚠ 可用显存只有 {free/1e9:.1f}GB,模型要 5.6GB,装不下会走内存"f"(单张会从 1 分钟变成十几分钟,最后超时)\n"f" 先关掉占显存的程序:浏览器硬件加速、其他 ComfyUI、游戏;\n"f" 还不够就把 --size 降到 768x1344")else:print(f"显存可用 {free/1e9:.1f}GB,够装模型")except Exception:pass# ---------- 5) 顺序出图(跨篇连着跑,不重启服务) ----------client_id = "dengshi_" + str(int(time.time()))queue = [(plan, t) for plan in plans for t in plan["todo"]]print(f"\n开始出图:待跑 {len(queue)} 张")saved, fails, t_start = 0, 0, time.time()stop = Falsefor k, (plan, t) in enumerate(queue):c = plan["chapter"]if k > 0:avg = (time.time() - t_start) / keta = int(avg * (len(queue) - k))eta_txt = f"剩余约 {eta//60}分{eta%60:02d}秒"else:eta_txt = "测速中"print(f"\n[{k+1}/{len(queue)}] {c['title']} #{t['idx']:02d} · {eta_txt}")print(f" {t['action'][:60]}")try:wf = build_workflow(t["prompt"], t["seed"], w, h, args.steps,f"dengshi_{safe_name(c['title'])}_{t['idx']:02d}",cfg=args.cfg, unet_name=unet_name,upscale=args.upscale, upscale_method=args.upscale_method)pid = submit_prompt(base, client_id, wf)outputs = wait_result(base, pid, timeout=args.timeout)imgs = outputs.get(SAVE_NODE_ID, {}).get("images", [])if not imgs:raise RuntimeError("没有拿到图片输出")for img in imgs:data = api_get_bytes(base, "/view", {"filename": img["filename"],"subfolder": img.get("subfolder", ""),"type": img.get("type", "output"),})with open(t["fpath"], "wb") as f:f.write(data)append_progress(plan["progress"], t["idx"])saved += 1print(f" ✓ {t['fname']} ({len(data)//1024} KB) · 已记账")except Exception as e:print(f" ✗ 失败:{e}")fails += 1if args.max_fails and fails >= args.max_fails:el = int(time.time() - t_start)print(f"\n{'='*52}")print(f"✗ 连续 {fails} 张失败,已中止(已耗时 {el//60} 分)")print(f" 已出的 {saved} 张都记在 progress 账本里,修好后原样重跑会自动续跑")print(" 排查:1) 看 dengshi_comfyui.log 末尾有没有 'loaded partially'(显存不够)")print(" 2) 关掉占显存的程序 3) 加 --size 768x1344")print(f"{'='*52}")stop = Truebreakelse:fails = 0# ---------- 6) 收尾 ----------for plan in plans:csv_path = os.path.join(plan["chapter"]["dir"], INDEX_TMPL.format(run=run))write_index_csv(csv_path, plan["tasks"])left = len([t for t in plan["tasks"]if not (os.path.isfile(t["fpath"]) and os.path.getsize(t["fpath"]) > 0)])print(f" {plan['chapter']['title']}:索引 {os.path.basename(csv_path)}"+ (f",还差 {left} 张" if left else ",全部完成"))if proc and not args.keep_server:print("关闭 ComfyUI ...")try:proc.terminate()proc.wait(timeout=20)except Exception:proc.kill()cost = int(time.time() - t_start)print(f"\n{'='*56}")print(f"完成:本次生成 {saved} 张,耗时 {cost//60}分{cost%60}秒"+ ("(已中止)" if stop else ""))print(f"{'='*56}")if __name__ == "__main__":main()
# 🌟 人间灯市 · 柔粉篇 🐰固定提示词:~~~超低角度仰拍广角镜头,七夕夏夜灯笼高挂的老商业街灯市,一位二十岁上下的年轻亚洲女性,鹅蛋脸杏眼,肤白如凝脂,身材高挑曼妙,肩窄腰细腿长,一双修长笔直的大腿完全裸露在外,腿部从大腿到脚踝全部可见,乌黑长发编成一条垂腰长辫,发间戴一对白色毛绒兔耳发饰,真人实拍,写实摄影风格,非插画非动漫,现代人穿现代时装,非汉服非古装,身穿一件高级定制时装屋级别的复杂结构连体短裙,一体式连身剪裁,上身是立体剪裁的抹胸式胸衣结构,多片式斜裁拼接,胸衣边缘层叠三层木耳边荷叶褶,胸前正中一朵手工钉珠立体缎面花朵,肩部两侧各垂下一片不对称的披肩式荷叶垂褶,一侧长垂至手肘一侧短垂至肩头,腰部收成极细的蜂腰,腰际一圈手工钉缝的珍珠与碎水晶腰封,腰封下方裙摆部分是多层蛋糕裙结构的迷你短裙,裙长极短短过膝盖之上,四层薄纱由内层粉白到外层浅粉层层渐变,每层纱缘以金线绣出细密的卷草纹并锁边,外层纱面满缀手工缝制的小水晶片与碎亮片,随动作折射细碎灯光,裙身侧面开一道高衩直抵腰际,衩口缘边三排细密的金线滚边,衩内是同色真丝衬裙,下身连体部分为高叉剪裁,双腿完全外露,腰后垂下两条不等长的缎面飘带拖尾,一条垂至膝弯一条垂至脚踝,飘带末端坠金珠流苏,配色比例粉白50%浅粉30%织金15%月白5%,发间除兔耳发饰外另有几支金花小簪与珍珠排珠点缀辫身,耳侧垂着长长的金流苏耳坠,颈间细金链叠戴三层,最下层坠一朵小金花,脚踩一双金线刺绣水晶扣的粉色缎面细高跟凉鞋,细带交叉缠上脚踝,裸露的纤细小腿与脚踝线条优美,腕间一对细金镯与一条金链手饰叠戴,全身除面部以外完全失焦虚化,唯脸部清晰,焦点精准锁定在面部,动态抓拍瞬间,肢体自然生动,重心偏移,修长裸腿的姿态每一张都完全不同,面部光影层次丰富,摊位暖金灯箱的柔和主光照亮面部,鼻梁颧骨细腻高光,脸颊晕染着灯笼般的暖粉环境反光,下颌隐入柔和阴影,暖金色逆光勾勒兔耳发饰、长辫、荷叶垂褶、腰后飘带与裸露长腿的轮廓光,胸衣上的钉珠与裙面水晶片被灯光照出星星点点的闪光,裸露的大腿小腿与脚踝被逆光镶上一圈金色光边,兔耳发饰被逆光照得边缘透出一圈柔光绒毛,发丝被逆光点燃成金色细丝,眼眸明亮含水光,瞳孔倒映细小灯笼光点与远处烟花彩色光斑,眼神光晶莹,嘴唇水润高光,皮肤细腻通透如凝脂泛着樱花般的粉润光泽,面部是画面唯一实焦区域,{动作},连体短裙的多层蛋糕纱裙与不对称垂褶随动作在焦外晕染成粉白与鎏金交融的光雾,裙面水晶亮片失焦炸开成细密的粉金星光光斑铺满身体,腰后飘带与金珠流苏化作流动的金色光丝,短裙下裸露的修长双腿在光雾中清晰可见,身体比背景更亮如一团裹在星光里的发光轮廓,背景老街灯市密集红灯笼串摊位招牌和虚化人群完全虚化成粉金橙暖光斑海洋,远处夜空烟花在焦外散成一圈彩色光斑光晕,圆形散景铺满画面,前景一层虚焦的水晶光斑,镜头暖粉眩光,整体粉白鎏金暖调,高级定制时装周压轴礼服感,华丽繁复又灵动,柔光溢出,高光泛粉金柔光与水晶闪光,极浅景深,大光圈f1.2,焦外成像如星光滤镜,柯达暖调胶片质感,胶片颗粒,伦勃朗式柔美布光,电影感35mm人像摄影,高定时装摄影质感,杰作,超高清细节~~~变量提示词:~~~【疯狂玩闹 5条】1. 双脚一前一后错开半步急停在街心,身体还保持着转身的角度,长辫与花瓣裙摆正甩到半空,金色饰件悬在光里2. 展开双臂踮脚走在灯笼光影的一线上,前脚掌着地后脚跟悬空,兔耳发饰微微一颤,像走在光的绳索上3. 屈膝蹲在街边,小狗正被搂在怀里仰头蹭她的下巴,粉裙在地面铺成一圈摊开的花瓣4. 正处于旋转的半途,粉裙旋成盛开的花,一条腿的脚尖点地,头微仰闭着眼,金耳坠横向飞起,扶在灯柱上的手刚碰到柱身5. 悬在半空的跳跃瞬间,双臂高举,双腿一前一后跨下三级台阶,裙摆向上荡开,金链在开衩处闪成一道光【馋嘴吃货 3条】6. 双腿并拢侧身蹲在糖画摊前,兔子糖画正咬掉一只耳朵举在嘴边,嘴角沾着糖渣,眼睛弯着7. 坐在摊前高脚凳上翘着腿悬空轻晃,一碗桂花甜汤捧在两手间,白汽正飘上她的睫毛,眼睛半弯着8. 酥山冰酪含在腮边,肩膀微微缩起,正眯眼打那个被冰到的哆嗦,眉头轻轻皱着【小情绪 3条】9. 双腿微屈重心后撤半步僵在原地,一手还提着裙摆,扭头看向骡子摊的方向,表情刚从惊转成不好意思的笑10. 双脚分开叉腰站着板板正正,下巴微抬嘴微张,卡壳的瞬间,兔耳发饰一歪,一脸认真地发懵11. 弯腰弓步单手拧着湿了一截的裙角,腮帮子鼓着,裙摆水珠正滴回水盆里,一脸心疼【安静许愿 3条】12. 一只脚踩在桥栏矮墩上另一条腿绷直脚尖点地,手搭在眉骨上远望灯市尽头,粉裙被风吹得贴向一侧,像月光里的小仙女13. 双腿并拢微微前倾弯腰,指尖正碰到兔子灯的纸耳朵,烛光从纸里透出来映在她脸上,眼神放空出神14. 后背贴着木门站着,一条腿屈膝脚掌蹬着门框另一条腿放松斜伸,闭着眼,裙上金纹在灯光下静静起伏【人灯互动 3条】15. 怀里抱着粉色兔子玩偶,重心刚从套圈的姿势弹回来,下巴扬起,眼睛亮得像偷到糖的小狐狸16. 俯身悬在星图摊上方,一条腿向后伸直绷着,指尖点在星图上,眼睫上落满星图反射的灯光17. 提着兔子灯双脚并拢蹦在半空,灯在手里晃出一线暖光,自己正咧嘴大笑,长辫扬起【收尾大动作 3条】18. 后腿蹬地前腿跨上,正跃上石桥最高一级台阶的瞬间,回身仰望满天金雨,兔耳发饰与烟花同辉19. 双腿交替腾空的大步奔跑中猛然回眸,前脚已刹住后脚还拖着惯性,粉裙与长辫在身后展开成飞旋的花雨20. 盘腿坐在货栈门槛上,一条小腿伸在街面,兔子灯摆在脚边台阶上,托着腮看灯市一盏一盏慢慢熄灭~~~## 简介~~~# 人间灯市 · 柔粉篇 🐰灯市第十三位,她不是从宫里来的,也不是从商队来的——她自己也不说从哪来,只说「很远很远的地方,有一片森林」。粉白抹胸花瓣裙,腰封上金纹流转,高开衩的裙摆露出踏过千山万水的双腿,头顶一对粉白兔耳发饰——通身都是她的秘密。她的玩法也和所有姊妹不同:吃糖画先咬兔耳朵、套圈专套兔子玩偶、自己转圈转到扶着灯柱直笑。最后坐在货栈门槛上,把兔子灯放在台阶上,托腮看灯市一盏一盏熄灭。十二位姊妹至此各有归属:石榴属宫宴的正红,夜宴属宴席的孔雀绿,月白属宫里的月光,黛蓝属于宫墙之外——**柔粉**属于森林与月光。她是十三位里最不像「人」的那个:跳石阶跳得最轻,落地却最稳,站在桥头时,风把裙摆吹成一朵开在夜里的花。别人把灯市当天上,她把一整片星斗森林穿在身上,来赴这一个夏夜的约。---两版结尾供选:- 走心版:「从森林走到人间要很多年,但为一盏灯停下来,只要一秒。」- 俏皮版:「夜宴:宫里规矩多吧?柔粉:巧了,我连门都还没找到。」---**系列档案**:灯市宇宙十三联达成(星河/月夜/银杏/霜星/墨竹/翡翠/石榴/玄夜/星河2.0/月白/夜宴/黛蓝/柔粉),新中式高定线十四员。柔粉(花间精灵)入列,正好补上灯市宇宙的最后一块拼图:森林。至此十三联灯市长卷圆满,齐了 🏮🌸✨---如需调整(比如更强调蝎子辫、改配色比例、或把兔耳改成更写实的发饰),告诉我即可!~~~