ARTICLE · 1281155
无界长文档解析 SOTA 模型登陆海光 DCU:Unlimited-OCR-2 官方协议全量复现(附全部命令)
description: 百度Unlimited-OCR-2(3B MoE/500M激活)无界长文档OCR大模型海光DCU全量复现:官方SGLang wheel+5处DCU补丁,MarathonDocBench官方协议逐指标对比,附完整部署命令。
2026 年 10 月 27 日,百度发布第二代长文档 OCR 大模型 Unlimited-OCR-2,同步放出超长文档解析基准 MarathonDocBench。这个模型用 SR-SWA 稀疏参考滑动窗口注意力,把超长文档的视觉注意力压缩成一组固定大小的"工作参考",实现了官方所说的"无界"(unlimited-horizon)文档解析。
我们在海光 DCU 上完成了它的完整适配:官方 SGLang wheel 起步,只加 5 处 DCU 补丁 + 1 个 aiter shim,以 serving 服务方式运行,按官方评测协议复现 MarathonDocBench 全量 100 篇文档,逐指标对比精度。本文给出全部部署命令——全部起点都是公开资源,照着做就能跑通。
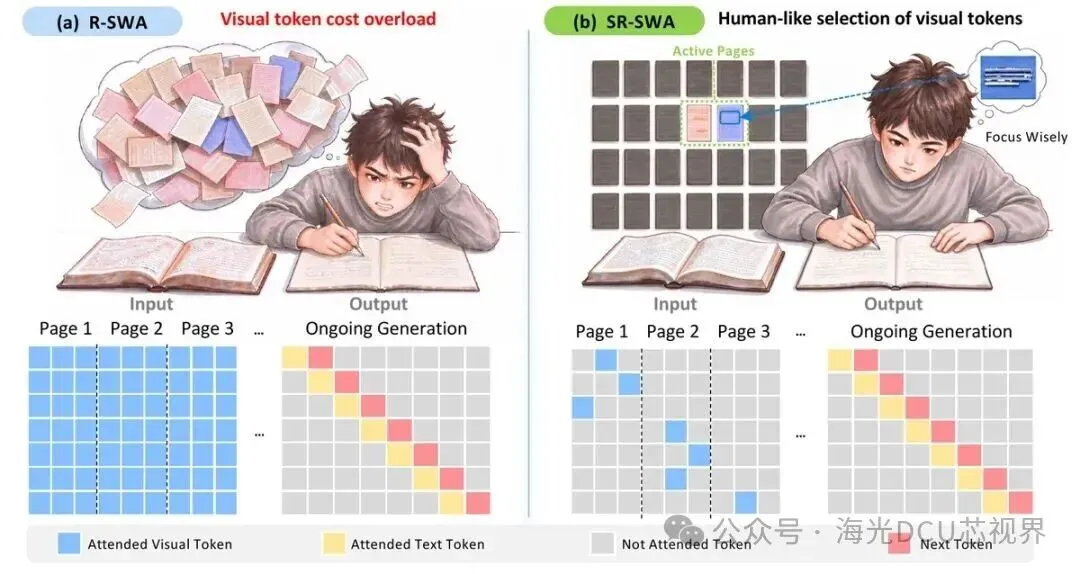
SR-SWA 原理:视觉 token 从成本过载到类人选择
1. SR-SWA(Sparse Reference Sliding Window Attention)——这是 Unlimited-OCR-2 的核心机制。传统滑动窗口注意力(R-SWA)下,文档越长,模型要为每一页维持完整的视觉 token,注意力成本随页数线性膨胀、生成开销失控(左图"Visual token cost overload");SR-SWA 把超长序列的文本-视觉注意力交互压缩到一组固定大小的工作参考(例如 512 token),让每一步的解码开销与内存占用基本不随文档长度变化(右图"Human-like selection of visual tokens")——官方口径是"effectively eliminating quadratic attention scaling and memory bottlenecks as documents grow",即有限上下文窗口内实现真正无界的文档解析(From Long- to Unlimited-Horizon Parsing)。
2. 3B MoE / 500M 激活。总参数 3B,每个 token 只激活 500M(DeepSeek-V2 风格 MoE)——长文档建模容量与单 token 推理成本之间的平衡,这是它"啃得动"几百页文档、又跑得动的基础。
3. 整篇文档一次请求。所有页面打包进一个请求(
4. 官方 SOTA。在官方 leaderboard 上,Unlimited-OCR-2 同时在"几十页档"(MPDocBench,Overall 84.6)与"上百页极限档"(MarathonDocBench,Overall 77.1)两个基准上排名第一,对前 SOTA 分别领先 +6.3 / +43.3——长文档上其他模型(包括各系旗舰大模型)普遍断崖,这个优势正是 SR-SWA 带来的。
官方 leaderboard 关键数字:
| 84.6 | ||||
| 77.1 |
起点全部是公开资源:光合社区官方镜像 + 官方 GitHub wheel + ModelScope 权重。不依赖任何内部产物。
sglang:0.5.12-ubuntu22.04-dtk2604-py3.10(自带 DTK 26.04 工具链:torch 2.10.0 / triton 3.5.0,Python 3.10) | |
PaddlePaddle/Unlimited-OCR-2(bf16) | |
docker pull harbor.sourcefind.cn:5443/hcu/admin/base/sglang:0.5.12-ubuntu22.04-dtk2604-py3.10docker run -d --name uocr2 --network bridge \ --security-opt seccomp=unconfined --security-opt label=disable \ --device /dev/kfd --device /dev/dri --cap-add SYS_PTRACE \ -v <权重目录>:/data <镜像> sleep infinity
seccomp unconfined + /dev/kfd 透传是 DCU 容器的标准配置;镜像自带 DTK 26.04,无需在宿主装工具链。
# 宿主机执行(/data 已挂载进容器)pip install modelscopemodelscope download --model PaddlePaddle/Unlimited-OCR-2 --local_dir <权重目录>/model
# ① 官方 UOCR2 SGLang wheel(官方仓库 wheel/ 目录;文件名随版本滚动,以下为发布时版本)cd /tmpwget "https://media.githubusercontent.com/media/baidu/Unlimited-OCR/main/wheel/sglang-0.5.20.dev13+g75b9b06b02-py3-none-any.whl"# ② 解包(wheel 就是 zip,内含 sglang/ 与 fastokens/ 两个包)mkdir -p /opt/uocr2_sgl && cd /opt/uocr2_sglunzip -o /tmp/sglang-*.whlcd -# ③ DCU 补丁(5 处,幂等脚本,全文见 3.1)mkdir -p /opt/patches# 将 apply_all_patches.py 放入 /opt/patches/python /opt/patches/apply_all_patches.py# ④ 依赖钉死目录:UOCR2 wheel 的验证依赖集(与官方镜像的 sglang 0.5.12 环境对齐,# 全部为公开 PyPI 包)。独立成目录、用 PYTHONPATH 覆盖,避免动镜像本体pip install -i https://mirrors.aliyun.com/pypi/simple/ --target /opt/uocr2_tf \ transformers==5.12.1 tokenizers==0.22.2 huggingface-hub==1.33.0 \ fastapi==0.116.1 uvicorn==0.54.0 xgrammar==0.2.8 fastokens==0.3.2 \ ninja==1.13.2 openai==3.39.0 outlines==1.3.3 mistral-common==1.12.0 \ msgspec==0.22.0 orjson==3.13.0 sentencepiece==0.2.2 pyzmq==26.4.0 \ interegular==0.3.3 partial-json-parser==0.2.1.1.post7 pybase64==1.5.1 \ python-multipart==0.0.32 anthropic==2.3.0 anyio==4.15.1 blobfile==3.3.0 \ distro==1.9.0 httpcore2==2.14.0 httpx2==2.14.0 idna==3.20 \ truststore==0.10.5 typing-extensions==4.16.0 setproctitle==1.3.8 certifi==2026.10.23# ⑤ aiter shim:官方 wheel 的 sglang/__init__.py 第一行就是 import aiter_shim——# 这个 shim 会扫描 sglang 代码树需要的所有 aiter 符号,对缺失部分补上安全桩。# 没有它,import sglang 直接失败(全文见 3.1)cp /opt/patches/aiter_shim.py /opt/uocr2_tf/# ⑥ tvm-ffi:wheel 声明 apache-tvm-ffi==0.1.11(xgrammar 的 load_lib_module 依赖它)pip install -i https://mirrors.aliyun.com/pypi/simple/ apache-tvm-ffi==0.1.11
# 容器内执行;多卡 = 每卡一个实例(改 PORT 与可见卡号)export HSA_VISIBLE_DEVICES=0 CUDA_VISIBLE_DEVICES=0export PYTHONPATH=/opt/uocr2_tf:/opt/uocr2_sgl# 页窗调度(官方 README 的 UOCR 服务参数)export SGLANG_UOCR_EANABLE_DOC_LIMIT=1 # 1 = 启用文档分窗export SGLANG_UOCR_DOC_GUNDAM_PAGE_WINDOW=10 # gundam 模式每窗 10 页export SGLANG_UOCR_DOC_BASE_PAGE_WINDOW=10 # base 模式每窗 10 页export SGLANG_UOCR_MAX_PAGE_TOKENS=20000# 镜像侧服务优化项export SGLANG_OPT_UOCR_SAM_REL_POS_BIAS_MB=64export SGLANG_UOCR_SHM_WRAP_MODEL_DATA=1export SGLANG_UOCR_SHM_WRAP_MIN_MB=1export SGLANG_VLM_CACHE_SIZE_MB=0export PYTORCH_CUDA_ALLOC_CONF=expandable_segments:Truepython -u -m sglang.launch_server \ --model-path /data/model --trust-remote-code \ --served-model-name Unlimited-OCR-2 --chat-template unlimited-ocr \ --tokenizer-backend fastokens --tokenizer-worker-num 8 \ --dtype bfloat16 --tp 1 --host 127.0.0.1 --port 30001 \ --mem-fraction-static 0.7 --max-running-requests 64 --max-prefill-tokens 2048 \ --enable-custom-logit-processor --enable-streaming-session --allow-auto-truncate \ --disable-radix-cache --mm-preprocess-cache-size-mb 0 \ --cuda-graph-backend-decode full --cuda-graph-max-bs-decode 64 \ --cuda-graph-backend-prefill full --cuda-graph-max-bs-prefill 2048 --cuda-graph-bs-prefill 1024 2048
DCU 侧说明:引擎首次初始化涉及 Triton JIT 编译,需要一段时间,留意日志出现 "The server is fired up and ready to roll!" 即就绪;cuda graph(decode/prefill full)在 DCU 上已验证可正常捕获。
# 官方仓库根目录的 infer.py + utils/process_unlimitedOCR2.py# 整篇文档一次请求(infer.py 内部把全部页面打包进一个请求)python infer.py --url 127.0.0.1:30001 --benchmark MarathonDocBench \ --dataset-root <MarathonDocBench 数据目录> --doc <文档 id> \ --concurrency 4 --raw-dir <raw 输出目录># 后处理:多页 raw 输出合并为最终 markdown(图片引用回填)python utils/process_unlimitedOCR2.py --infer-dir <raw 输出目录> --out-dir <md 输出目录>
MarathonDocBench 数据:官方发布在 Hugging Face(baidu/MarathonDocBench),ModelScope 有镜像,100 篇文档、页级 GT(文本/表格/公式/图/阅读顺序/标题树)。
官方 wheel 的 Triton kernel 层在 DCU(triton 3.5 / torch 2.10)上有 5 处兼容问题,全部是"能定位、能小改、语义不变"的适配:
tl | import tritonimport triton.language as tl 提升到模块顶部 | ||
_row 定义在函数体内部,DCU 上 triton 编译顺序差异使其先被引用后定义 | |||
max(16, next_power_of_2(...)) | |||
torch.version.hip_PDL_SUPPORTED=False | |||
residual <- x+residual, x <- rmsnorm(residual)*weight,语义不变) |
补丁脚本(幂等,重复执行安全;在容器内对 /opt/uocr2_sgl 生效):
#!/usr/bin/env python3# UOCR2 @ DCU 合并补丁脚本(P1–P5,幂等,可重复执行)。在容器内运行:python apply_all_patches.pyimport sys, re, subprocessSGL = "/opt/uocr2_sgl"results = []def patch(name, path, check, apply_fn): src = open(path).read() if check(src): results.append((name, "SKIP (already applied)")) return src = apply_fn(src) assert check(src), name + " verify failed" open(path, "w").write(src) results.append((name, "APPLIED"))P1F = SGL + "/sglang/srt/layers/attention/unlimited_dash_ops/page2d_rope.py"def p1_check(src): ls = src.split("\n") return "import triton" in ls and "import triton.language as tl" in lsdef p1_apply(src): ls = src.split("\n") ins = None for i, l in enumerate(ls): if l.startswith("from __future__"): ins = i + 1 break if ins is None: ins = len(ls) ls = ls[:ins] + ["import triton", "import triton.language as tl"] + ls[ins:] return "\n".join(ls)def p2_check(src): return any(not l.startswith(" ") and l.startswith("def _row(") for l in src.split("\n"))def p2_apply(src): import ast lines = src.split("\n") tree = ast.parse(src) t = None for node in ast.walk(tree): if isinstance(node, ast.FunctionDef) and node.name == "_row": t = node break assert t is not None and t.col_offset > 0 start = t.decorator_list[0].lineno - 1 end = t.end_lineno ind = " " * t.col_offset block = [] for l in lines[start:end]: if l.strip(): assert l.startswith(ind), repr(l) block.append(l[len(ind):]) else: block.append("") del lines[start:end] ins = next(i for i, l in enumerate(lines) if l.startswith("def _get_rope_kernel_pair")) lines = lines[:ins] + block + [""] + lines[ins:] return "\n".join(lines)P3F = SGL + "/sglang/srt/layers/attention/unlimited_dash_ops/attend_triton.py"P3MARK = "max(16, triton.next_power_of_2(args[\"gqa_group_size\"]))"def p3_check(src): return src.count(P3MARK) >= 2def p3_apply(src): l1 = " \"BLOCK_SIZE_H\": lambda args: triton.next_power_of_2(args[\"gqa_group_size\"])" n1 = " \"BLOCK_SIZE_H\": lambda args: max(16, triton.next_power_of_2(args[\"gqa_group_size\"]))" l2 = " * triton.next_power_of_2(args[\"gqa_group_size\"])" n2 = " * max(16, triton.next_power_of_2(args[\"gqa_group_size\"]))" assert src.count(l1) == 1 and src.count(l2) == 1, "P3 pattern mismatch" return src.replace(l1, n1).replace(l2, n2)P4F = SGL + "/sglang/srt/layers/attention/unlimited_dash_ops/common.py"def p4_check(src): i = src.find("def _arch_supports_pdl") j = src.find("return _PDL_SUPPORTED", i) if i >= 0 else -1 return i >= 0 and j > i and "torch.version.hip is not None" in src[i:j]def p4_apply(src): old = " _PDL_SUPPORTED = _compute_pdl_support()\n" new = " if torch.version.hip is not None:\n _PDL_SUPPORTED = False\n else:\n _PDL_SUPPORTED = _compute_pdl_support()\n" assert src.count(old) == 1, "P4 pattern mismatch" return src.replace(old, new)P5F = SGL + "/sglang/srt/layers/layernorm.py"P5MARK = "# vllm-das API: 4-arg in-place"def p5_check(src): return src.count(P5MARK) == 2def p5_apply(src): o1 = " out = torch.empty_like(x)\n residual_out = torch.empty_like(x)\n if post_residual_addition is not None:\n residual = residual + post_residual_addition\n fused_add_rms_norm(\n out, x, residual_out, residual, self.weight.data, self.variance_epsilon\n )\n return out, residual_out\n out = torch.empty_like(x)\n rms_norm(out, x, self.weight.data, self.variance_epsilon)\n return out" n1 = " if post_residual_addition is not None:\n residual = residual + post_residual_addition\n # vllm-das API: 4-arg in-place; residual <- x + residual, x <- rmsnorm(residual) * weight\n fused_add_rms_norm(x, residual, self.weight.data, self.variance_epsilon)\n return x, residual\n out = torch.empty_like(x)\n rms_norm(out, x, self.weight.data, self.variance_epsilon)\n return out" o2 = " out = torch.empty_like(x)\n residual_out = torch.empty_like(x)\n if post_residual_addition is not None:\n residual = residual + post_residual_addition\n fused_add_rms_norm(\n out, x, residual_out, residual, w, self.variance_epsilon\n )\n return out, residual_out" n2 = " if post_residual_addition is not None:\n residual = residual + post_residual_addition\n # vllm-das API: 4-arg in-place; residual <- x + residual, x <- rmsnorm(residual) * w\n fused_add_rms_norm(x, residual, w, self.variance_epsilon)\n return x, residual" assert src.count(o1) == 1 and src.count(o2) == 1, "P5 pattern mismatch" return src.replace(o1, n1).replace(o2, n2)patch("P1 page2d_rope module-level tl imports", P1F, p1_check, p1_apply)patch("P2 page2d_rope hoist _row", P1F, p2_check, p2_apply)patch("P3 attend_triton BLOCK_SIZE floor 16", P3F, p3_check, p3_apply)patch("P4 common.py PDL off on HIP", P4F, p4_check, p4_apply)patch("P5 layernorm vllm 4-arg calls", P5F, p5_check, p5_apply)r = subprocess.run(["python", "-m", "py_compile", P1F, P3F, P4F, P5F], capture_output=True, text=True)results.append(("py_compile", "OK" if r.returncode == 0 else "FAIL " + r.stderr[:300]))for name, st in results: print(name, "->", st)sys.exit(0 if all(st in ("APPLIED", "SKIP (already applied)", "OK") for _, st in results) else 1)
aiter shim(61 行,官方 wheel 自带 import 钩子,DCU 上缺失 aiter 符号时兜底):
import sys, types, re, os_BASE = "/opt/uocr2_sgl/sglang/srt"files = []for root, _dirs, fnames in os.walk(_BASE): for fn in fnames: if fn.endswith(".py"): files.append(os.path.join(root, fn))needed = {}for path in files: try: src = open(path).read() except Exception: continue for m in re.finditer(r"^\s*from (aiter[\w.]+) import ([^\n]+)$", src, re.M): mod, names = m.group(1), m.group(2) names = names.strip().strip("(").strip(")") for n in names.split(","): n = n.strip().split(" as ")[0].strip() if n: needed.setdefault(mod, set()).add(n) for m in re.finditer(r"^\s*from (aiter[\w.]+) import \(([^)]*)\)", src, re.M | re.S): mod, names = m.group(1), m.group(2) for n in names.split(","): n = n.strip().split(" as ")[0].strip() if n: needed.setdefault(mod, set()).add(n)def _dummy(name): def _f(*a, **k): raise RuntimeError("aiter shim: %s not available" % name) return _ffor mod, names in needed.items(): if mod in sys.modules: continue try: __import__(mod) continue except Exception: pass parts = mod.split(".") for i in range(1, len(parts) + 1): sub = ".".join(parts[:i]) if sub in sys.modules: continue try: __import__(sub) except Exception: m = types.ModuleType(sub) m.__path__ = [] sys.modules[sub] = m parent = sys.modules.get(".".join(parts[: i - 1])) if parent is not None: setattr(parent, parts[i - 1], m) leaf = sys.modules[mod] for n in names: if not hasattr(leaf, n): setattr(leaf, n, _dummy(n))print("AITER_SHIM_OK modules=%d" % len(needed))
ldd 缺 libcudart.so.13 / libtorch_cuda.so;且 sglang 无关模块在 import sglang 时就会 import 它,起服务直接崩 | ||
tvm_ffi.libinfo.load_lib_module() 缺 extra_lib_paths 参数,TypeError | apache-tvm-ffi==0.1.11(公开 PyPI 可取) | |
MPDocBench 工具包 utils/extract.py(L282)的表格扫描正则在几百页的超长 md 上触发指数级回溯——py-spy 实测单篇文档卡在这个正则上 1 小时以上(评测假死)。处理:改成等价的逐行线性匹配(语义不变,原文件留备份)。这类"评测工具在超长输入上退化"的坑在跑极限基准时很常见,建议评测前先 py-spy 看进程到底卡在哪。
评测协议与官方 leaderboard 逐字一致:官方 infer.py(零改动)→ process_unlimitedOCR2.py → MPDocBench 工具包(match_method: quick_match),8 项指标配置如下:
end2end_eval: metrics: text_block: metric: - Edit_dist merged_text_block: metric: - Edit_dist display_formula: metric: - CDM table: metric: - TEDS merged_table: metric: - TEDS reading_order: metric: - Edit_dist head: metric: - HeadTEDS figure: metric: - FigureF1 dataset: dataset_name: end2end_dataset ground_truth: data_path: <MarathonDocBench 数据目录>/MarathonDocBench.json prediction: data_path: <输出目录>/MarathonDocBench_pred match_method: quick_match
评测环境(工具包超时/并行参数,官方规则内):MPDOC_EVAL_NPROC=32 MPDOC_MATCH_TIMEOUT=1800 MPDOC_DOC_BUDGET=0 MPDOC_TEDS_NPROC=32 MPDOC_TEDS_TIMEOUT=300,然后 python pdf_validation.py --config <上述 yaml>。
Overall 口径 = 官方 leaderboard 公式(8 项 score 均值:(1−TextEdit)×100、(1−T-TextEdit)×100、CDM、TEDS、T-TableTEDS、FigureF1、(1−ReadOrder)×100、HeadTEDS;公式经 leaderboard 官方各行反推验证)。
按上述口径,海光 DCU 实测 Overall 为 73.03。核心指标如下:
| +7.53 | |||
| +0.19 |
结构类指标好于官方:T-TableTEDS(跨页合并表格结构)比官方 leaderboard 高 7.53,HeadingTEDS 持平微超——表格结构保持与标题树能力在海光 DCU 上完整复现,且表现更好。
评测说明:
海光DCU开发者社区二维码